
Our Rust WebSocket service and our Kafka relay now live on one rented server with 2 vCPUs, 8 GiB of memory, and two neighbours we didn't put there.
That last part is the one I nearly got wrong. Twice.
Hearso is standup trivia: a host opens a room, teammates join with a code, and ten questions run on a server clock. Today every production room still polls our Next.js app on Vercel. The VPS is where rooms go when they stop polling.
So I wanted three answers before we trust it. How far is the database? Can we see what the box is doing? And what happens to a game when it breaks?
I used a ten-line TCP probe, Grafana Alloy shipping to Grafana Cloud, a bot benchmark, and a lot of reading what was already on the box before changing it.
Short answer: so far, yes, with room to spare. At 03:39Z on 2026-09-27 the box read a load average of 0.07, with 6,716 of 7,940 MiB available. The database is 61-73 ms away by TCP. With the room loop's polling removed, the median answer took 328 ms from there.
But production rooms do not use the box today. We switched production to WebSockets once, on 2026-09-23, and switched it back nine minutes later. And our own deploy kit came within one command of overwriting someone else's config.
The failover we designed is partly built now. I'll mark exactly which parts, with dates.
It follows Hearso answers still ride a 1.5-second poll. Here's the socket path, My soak runner said FAIL at minute 30. The service was fine and Freeing port 8080 shut down Docker, and 28 containers with it: the same service, now off the laptop.
Why move real-time off polling at all?
Every open room page asks Next.js for the room's state every 1,500 ms. Each ask is an HTTP request to Vercel and at least one query to Supabase. That's 40 requests a minute per player, whatever is happening in the game.
A WebSocket is the other way round. Think of a phone call instead of postcards: the connection stays open, and the server speaks when something changes. Our Rust service, hearso-rt, holds one socket per player and pushes each change once.
We moved two services to a VPS, for three reasons:
- Cost. Every poll runs on Vercel, and we pay for that compute.
- Fewer HTTP calls. A socket turns 40 requests a minute per player into a push per change, plus a keep-alive.
- Decoupling. Real-time rooms and the event log are separate services with their own failure modes. They should not share a deploy with the web app.
Each reason has a price, and the rest of this post is about paying it. The box is far from the database, it has neighbours, and it is one machine.
The second service is the Kafka event-log relay. When a WebSocket game finishes, hearso-rt writes a row to an outbox table in the same transaction. The relay reads that outbox and publishes each event to a Redpanda broker, a Kafka-compatible server, on the same box.
The box wasn't empty, and that mattered twice
The VPS is a Hostinger "KVM 2": 2 vCPU and 8 GiB of RAM (7,940 MiB usable), in Phoenix, Arizona. The database is Supabase Postgres in us-east-1, in Virginia.
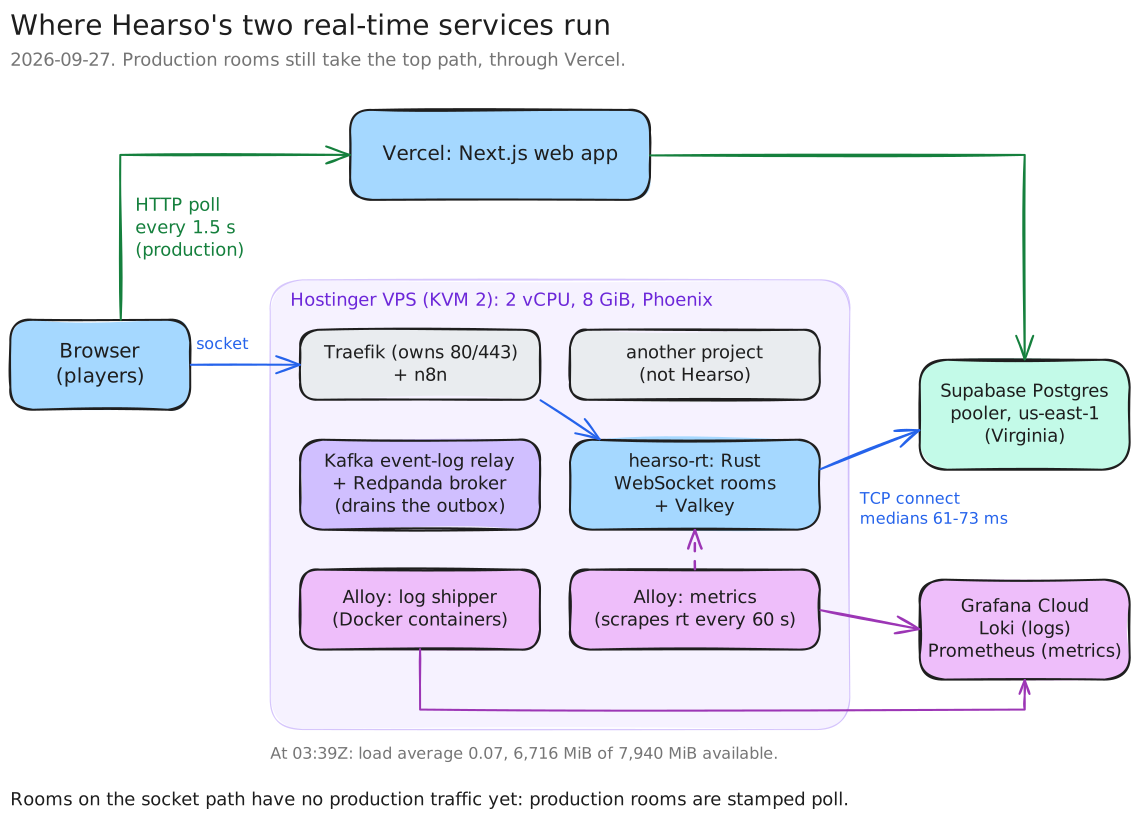
Figure 1. What runs where on 2026-09-28 (UTC), read from the container list on the VPS. Production rooms still take the top path.
| On the box | What it is | Ours? |
|---|---|---|
| Traefik + n8n | A reverse proxy that owns ports 80 and 443, and an automation tool | No, it was there first |
| Another project | A separate app with its own cache | No |
| hearso-rt + Valkey | The Rust WebSocket game service and its cache | Yes |
| Kafka relays + Redpanda | hearso-relay-vps for DEV and hearso-relay-prod for PROD read their outboxes and publish to the broker | Yes; the PROD relay since 2026-09-27 |
hearso-alloy | Ships container logs to Grafana Cloud Loki | Yes, set up separately, earlier |
hearso-alloy-metrics-1 | Scrapes hearso-rt's metrics every 60 s | Yes, new on 2026-09-27 |
hearso-alloy-relays | Scrapes both relays, labelled by environment | Yes, new on 2026-09-27 |
hearso-alloy-host + a socket proxy | Host and per-container metrics | Yes, new on 2026-09-28 |
| Uptime Kuma | Four uptime monitors behind our public status page | Yes, new on 2026-09-28 |
The relays got their own Alloy for a boring reason: the collector in hearso-rt's network namespace could not reach the relays' published port. The connection timed out, so the third Alloy sits on the relays' Docker network instead.
Here's the first time the neighbours mattered, on 2026-09-22. Our deploy kit had been written for an empty machine, and it started its own proxy on port 443. Traefik already held 443 for n8n, so running the kit as written would have collided with it. We added a router to the existing Traefik instead, and nothing of the other projects was restarted.
The second time is below.
We switched production to WebSockets for nine minutes
The day after that first deploy, at about 01:45Z on 2026-09-23, we switched production to WebSockets. The whole path worked: a room created through the production API was stamped ws, its socket upgrade answered 101, and the VPS logged the room's actor starting.
We switched it back at about 01:54Z. A WebSocket game's scores reached no leaderboard yet, so a real player finishing one would have lost theirs. The switch was one setting, and everything else stayed in place.
The WebSocket testing moved to DEV, and the bot runs there found the bigger problem. Commands went unanswered for so long that the bots reported them as server errors. None were. Our client gives up after 10 s, and it counted that timeout as a 5xx. (It sent me looking in exactly the wrong place.)
We ran an A/B test with the same binary, the same bots and the same commands. Only the database changed:
room.answer reply | DEV database through the pooler (38 ms from the laptop) | Local Postgres |
|---|---|---|
| p50 | 3,658 ms, one run 10,255 ms | 7 ms |
| Slowest | 20,572 ms | 21 ms |
| Unanswered within 10 s | 22 of 41 | 0 |
The cause was the room actor. It woke every 250 ms and re-read the whole room, three queries at a time, up to three times per tick. At 38 ms a round trip, that is about 342 ms of database time in a 250 ms period, so commands queued behind it. One game took 2,511 database transactions.
Two fixes followed:
- PR #10, merged 2026-09-23, made the tick read the room once and cache the question deck. On the same rig the median fell to 1,157-1,277 ms, the slowest answer to 2,805 ms, and nothing went unanswered. (Its first commit alone had reached 2,702 ms.) An improvement, not a fix.
- PR #11 (
ad2624f), merged 2026-09-24, removed polling. The actor wakes only for a command, a deadline, or a signal that someone else changed the room.
When this post was first written, the VPS still ran a build from before PR #11: 700ae6c5, 22 commits behind. So the rooms on the VPS still polled, and nobody had measured command latency against a remote database on a build with the fix.
(Update, 2026-09-27: build 6ae8af3a, which contains PR #11, was deployed that night and measured against the PROD database. The median room.answer reply was 328 ms, the slowest 969 ms, and no command timed out. The method and confounds are in One database round trip was 17% of our median answer. Update, 2026-09-28: a one-line pool change saved one more round trip per answer on DEV, measured in the same post.)
One more lesson from that night. /health stayed green the whole time. A health check asks "is the process up?", and the answer was yes. It never asked whether a command gets an answer, and that is the thing a player needs. The same gap comes back in the failover below.
How far is the database, really?
The A/B made one thing plain: the trip to the database sets the pace of a room. So the next number to get was that trip from the VPS itself.
At 03:39Z on 2026-09-27, I ran our probe on the VPS against Supabase's connection pooler in us-east-1. It opens a TCP connection ten times and times each one. It sends no password and no query.
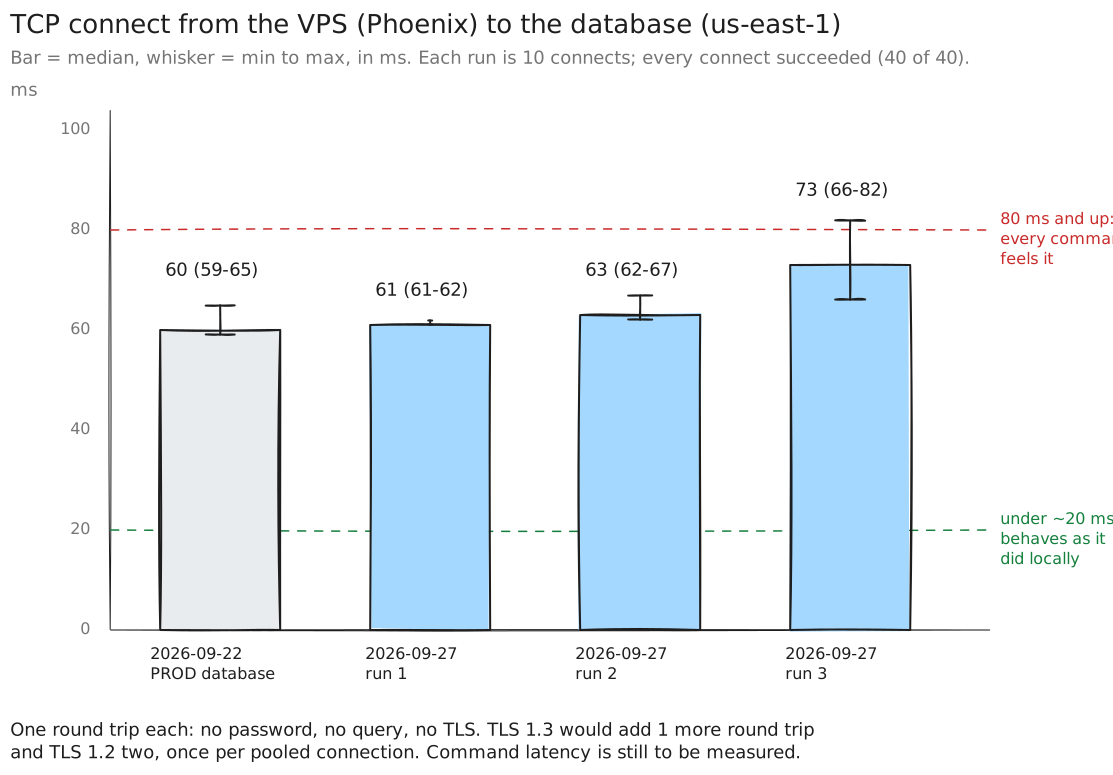
Figure 2. TCP connect time, VPS (Phoenix) to the database (us-east-1), 10 connects per run, 40 of 40 succeeded. 2026-09-22 reading from the operations notes (the production database); 2026-09-27 runs at 03:39Z.
| Run (UTC) | Succeeded | Min | Median | Max |
|---|---|---|---|---|
| 2026-09-22 | 10 of 10 | 59 ms | 60 ms | 65 ms |
| 2026-09-27 03:39Z, run 1 | 10 of 10 | 61 ms | 61 ms | 62 ms |
| 2026-09-27 03:39Z, run 2 | 10 of 10 | 62 ms | 63 ms | 67 ms |
| 2026-09-27 03:39Z, run 3 | 10 of 10 | 66 ms | 73 ms | 82 ms |
The probe prints its own guide. Under about 20 ms, the service behaves as it did locally. At 80 ms and up, every command feels it. We're between the two, closer to the second.
What a TCP number tells you. A TCP connect is one round trip: a SYN out, a SYN-ACK back. So it's the floor for anything the service does with the database. Nothing can be faster than one trip to Virginia and back.
What it doesn't. It says nothing about a query, and our probe measured TCP only, not TLS. A full TLS 1.3 handshake adds one more round trip, and TLS 1.2 adds two, once per pooled connection, not per query. (The probe's own comment said "two or three"; that overstated it.) Each command still makes several database round trips, and commands in one room run one at a time. So what a player feels is some multiple of 61-73 ms, plus query time, plus queueing: the benchmark post measures exactly that.
Our metrics deploy nearly overwrote the log shipper
A probe is one reading, taken by hand. For the rest of the time, the box has to report on itself.
Grafana Cloud is our backend. We decided not to add OpenTelemetry to the web app on Vercel, because it adds cost there. Observability lives with the VPS services instead.
Two kinds of signal matter. Logs are events with detail: this room opened, this socket closed. Metrics are numbers sampled over time: how many sessions are open right now. Loki stores logs; Prometheus stores metrics.
When I went to add metrics, there was already an Alloy on the box: hearso-alloy, Grafana Alloy v1.10.0, up for two days. Its config was three blocks: discover Docker containers, read their logs, write to Loki. It shipped logs only.
Our kit's first draft would have broken it in two ways:
- It copied our metrics config to the same path the log shipper reads. The deploy would have overwritten the log shipper's config.
- Its rollback removed "the container whose Compose service label is
alloy". The log shipper carries that label too, so undoing our change could have deleted the log shipper.
Both came from one mistake: I named things as if the box were ours alone. The fix was to rename everything we own. The service became alloy-metrics, with its own config directory and volume, and every container filter now also matches our Compose project. A rollback can only reach what we deployed.
The four checks before deploying
- Scope of
--remove-orphans. It could only reach hearso-rt and Valkey. The Kafka relay, the log shipper and n8n are separate Compose projects. - No restart of hearso-rt. Its section of the Compose file was byte-identical to the server's copy, so Compose would not recreate it and no socket would drop.
- Nothing overwritten. The credentials file for Grafana Cloud did not exist yet on the server.
- A way back. The server's kit files were backed up first, and every copied file's checksum matched the local copy.
We then redeployed the same hearso-rt build, 700ae6c5. Compose created one container, hearso-alloy-metrics-1, and hearso-rt stayed the same container, up for 3 days.
What "up = 1" means
Prometheus records a metric called up for every target it scrapes: 1 if the scrape worked, 0 if it did not. It's the first thing to check, because every other series depends on it.
The metrics collector logged its first line at 02:31:25Z. Grafana Cloud answered up{service="hearso-rt",environment="production"} = 1 at 02:32:36Z, 71 seconds later. Alloy logged no errors.
Why production shows 0 sessions, correctly
Grafana then held six hearso-rt series, and hearso_rt_active_sessions read 0. A production round was played at 02:51Z, and the number stayed at 0.
That zero is correct. Production rooms are still polled, so their traffic goes browser to Vercel to Supabase and never touches the VPS. A zero on a dashboard needs a reason written next to it. Ours is "no production room uses this path yet".
The build running then exposed one gauge; the latency histograms from PR #14 were due with the next build. (Update, 2026-09-27: they arrived with 6ae8af3a. Grafana went from 6 hearso-rt series to 688, in 9 histogram families.)
What can we see on the box now?
More than when I started. Each of these is dated, because they landed after the first version of this post:
| When (UTC) | What we can see now | How |
|---|---|---|
| 2026-09-27 | Room events in Loki, with a timestamp and the room code | hearso-rt PRs #17 and #18 (build 0326e143) write structured JSON to stdout; the log shipper sends it on |
| 2026-09-27 | A "Hearso · Live rooms" dashboard: a room's timeline by room code, errors, relay panels with an environment picker | Our Grafana deploy kit |
| 2026-09-27 | 14 alert rules, sending email; 17 by 2026-09-28 00:35Z | The same kit, plus 3 leaderboard rules |
| 2026-09-28 | Host and per-container metrics: 310 series (198 host, 112 for 13 containers); 6.7 GB of memory available at 17:19Z | hearso-alloy-host and a Docker socket proxy that listed containers and refused every write we tried |
| 2026-09-28 | A public status page with four monitors: Website, Live games, Leaderboards, Score delivery | Uptime Kuma on the VPS; Traefik exposes only its status JSON |
The log shipper also drops the relays' preview lines and idle passes, and masks player ids inside command ids.
What still breaks it
- One box. A single VPS cannot be load-balanced. If it goes down, both real-time services go down with it.
- Admin access needed a person. On 2026-09-26, SSH to the box went through Tailscale in
checkmode: each session needed a browser sign-in, which an automated agent cannot complete. (Update, 2026-09-28: automated deploys over SSH ran on 2026-09-27 and 2026-09-28, so this changed. I have not re-read the tailnet policy to say exactly how.) - hearso-rt logged only to a file. It wrote JSON lines inside its container, and
docker logswas empty, so the log shipper collected nothing from it. The lines also carried no timestamp and no room code. (Update, 2026-09-27: fixed by PRs #17 and #18, above.) - Room codes belong in logs, not in metric labels. Every distinct label value creates a new time series. Every room has a new code, so as a label they grow without limit, and every active series counts against our Grafana Cloud usage. Counts like "rooms open" are metrics. "What happened in room X" is a log search.
How much of the failover exists?
One box that can go down is why moving rooms onto it needs a way back. Step 4 of our plan is moving production rooms onto WebSockets in a way we can control and undo, in the parts 4a to 4e below. On 2026-09-27 this whole section was a plan. On 2026-09-28, part of it was built and merged. Here's the honest status of each part, as of 19:00Z that day:
| Part | What it does | Status on 2026-09-28 |
|---|---|---|
| 4a. Transport dial | A setting on our /ops page sends 0, ops-only, 10, 50 or 100% of new rooms to WebSockets, with a confirm word, a cooldown and an audit entry. Servers cache it for 15 s | Merged (web #530, 18:25Z). Set to 0. Reaches production with the next web release. Percentages stay locked in the database until the next change (PR-C) lets the dial raise to them when rt's heartbeat is healthy; the chooser already requires a healthy heartbeat (PR-B) |
| 4b. Automatic failover | Room creation reads rt's heartbeat from the database. Unknown, stale or unhealthy means the room polls | Merged (web #531 and rt #22, about 19:00Z). Live: the rt build that writes the heartbeat was deployed at about 19:25Z, and its first beat reached PROD within seconds |
| 4c. High-traffic mode | Caps on rooms created per minute and on concurrent WebSocket rooms, switches to turn off share cards, pop-ups, replay and sound files, and a maintenance banner | Planned |
| 4d. Recovery without AWS | Rooms are durable in Supabase. The outbox holds events while the relay is down, and they drain later. The VPS is rebuilt from the kit | Planned |
| 4e. A second VPS | Rooms split across two boxes | Only if traffic demands it |
The failover design changed on the way, and it's worth saying why. The first plan had room creation call hearso-rt's /ready with a short timeout. Reading the code on 2026-09-27, we found /ready always answered 200 and listened only on the container's loopback, so Vercel could never reach it. A health check that cannot fail cannot drive a failover. So hearso-rt now writes a heartbeat row, and the database clock decides whether it is fresh.
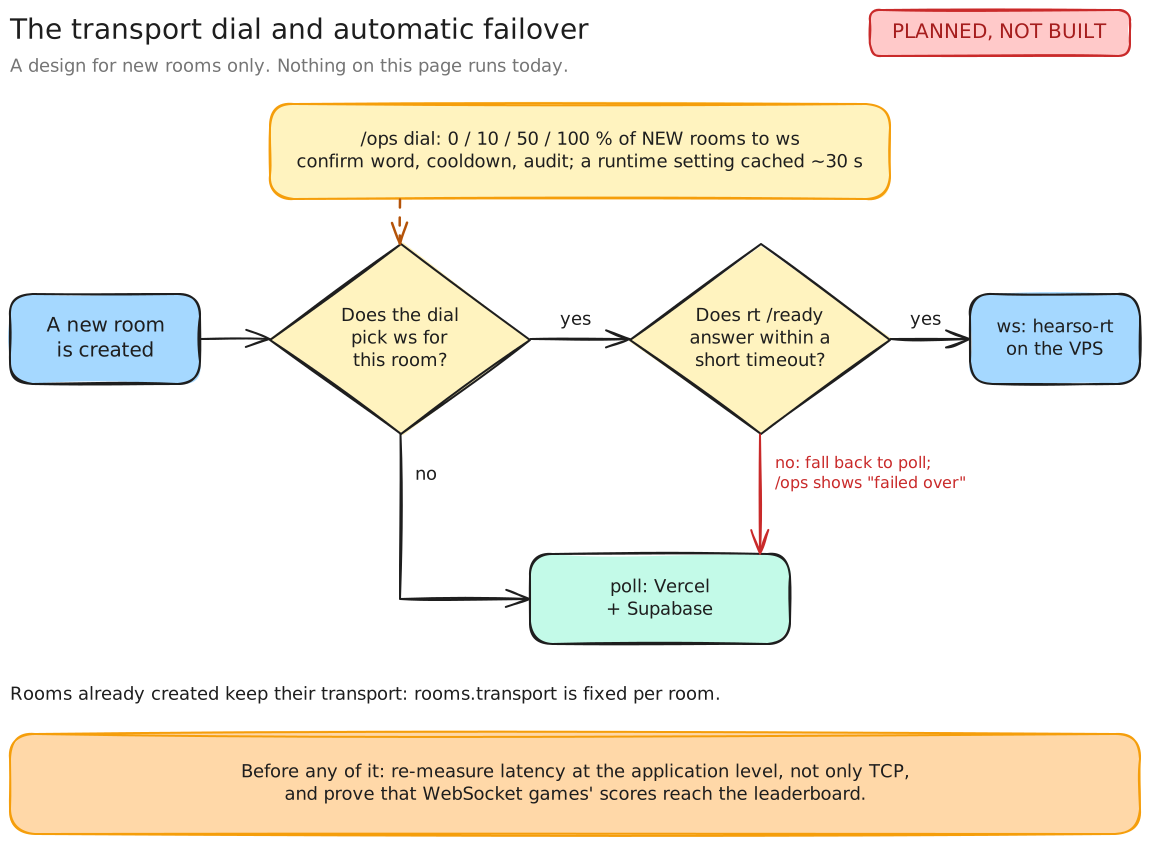
Figure 3. The transport dial and its failover as merged on 2026-09-28 (UTC). The dial sits at 0, so every room polls; a room keeps the transport it was created with.
Prerequisites that still stand. A real WebSocket game's score must be seen reaching the production leaderboard. The first step after the dial is ops-only: one real game, traced end to end.
4d has a known gap. A WebSocket room that is mid-game when the VPS dies is stranded until the poll path can adopt it, and nothing adopts it today. We'll investigate that, then rehearse the whole recovery as a drill on DEV before trusting it.
So, the three questions from the top. The database is 61-73 ms away, and that trip, not the size of the box, is what a command pays for. We can see the box now. What happens to a game when it breaks is the answer still open: a new room would fall back to polling, and a room caught mid-game would not.
Predictions vs outcome
| Prediction | What happened | Right? |
|---|---|---|
| Production could switch to WebSockets on 2026-09-23 | Switched back after nine minutes: WebSocket scores reached no leaderboard | No |
| The bots' "5xx" were server errors | They were 10 s client timeouts; no 5xx frame was ever captured | No |
| The deploy kit could run as written | It would have collided with Traefik on 443, then overwritten the log shipper's config | No |
| At 60 ms, production WebSockets would be slower than the laptop's 38 ms numbers (PR #10) | Slower per round trip, yes; but with polling gone, the median answer was 328 ms and nothing timed out | Half |
| A TLS session adds two or three round trips (the probe's comment) | One for TLS 1.3, two for TLS 1.2, once per pooled connection | No |
| The latency histograms arrive with the next rt build | They did: 6 series became 688 with 6ae8af3a | Yes |
Failover can use rt's /ready | /ready always said 200, on loopback only; failover now reads a heartbeat | No |
Key takeaways
- Read the box before deploying to it. Twice, a kit written for an empty machine would have hit something already running.
- Name and scope what you own. A rollback filtered on a generic label can delete someone else's container; filter on your own project too.
- Don't trust a health check that cannot fail.
/healthwas green while half of one run's commands went unanswered, and/readyanswered 200 no matter what. - Count a timeout as a timeout. Calling "no reply in 10 s" a 5xx sent us looking in the wrong place.
- Treat a TCP number as a floor, not a verdict. 61-73 ms is the minimum a query can cost, not what a player feels.
- Keep the switch one setting. The nine-minute production flip was easy to undo because only one value changed.
What I'd do next
- Done (2026-09-27): measure command latency from the VPS against the remote database, on the build with PR #11. Median 328 ms.
- Prove a WebSocket game's score reaches the production leaderboard, with the dial at
ops-onlyand one real game. - Done (2026-09-27): ship the next hearso-rt build, so the histograms from PR #14 reach Grafana.
- Release the dial with the next web release. (Done on 2026-09-28: the rt build that writes the heartbeat is deployed.)
- Build high-traffic mode (4c), with its ceiling taken from a capacity measurement, not a guess.
- Run the recovery drill on DEV, including a room that is mid-game when the service stops.
How we measured
- TCP probe.
measure-db-latency.shon the VPS opens ten TCP connections in a row to the database pooler and prints min, median and max. It sends no credentials and runs no query. Three runs from 03:38:59Z to 03:39:01Z on 2026-09-27. - The box. Load average and memory from the same run's output; the container list read on the VPS on 2026-09-26 and 2026-09-27, and again during the 2026-09-28 job.
- Metrics.
upand the series counts from Grafana Cloud queries, with the collectors' own logs for errors. - Command latency. Not measured here; see the benchmark post.
- What we did not test. Any production WebSocket traffic, the box under load, a VPS failure, or the recovery drill.
Evidence
All times UTC.
- The box and its neighbours (Figure 1, first table): container list and system readings on the VPS, 2026-09-26 to 2026-09-28; operations notes, 2026-09-22 (Traefik owning 80 and 443, the kit written for an empty box, the router added to the existing Traefik). Load average 0.07, 7,940 MiB total, 6,716 MiB available, and the Phoenix location: the latency run's output at 03:39:01Z on 2026-09-27. The relays and their Alloy: handoff entry 07:45Z on 2026-09-27.
- The 1,500 ms poll and 40 requests a minute:
POLL_MSinapp/room/[roomId]/room-client.tsx; 60,000 / 1,500 = 40. - The production flip and revert: operations notes, 2026-09-23. Flip at about 01:45Z, a production room stamped
ws, a 101 upgrade and the actor start logged on the VPS; revert at about 01:54Z because WebSocket games' scores reached no leaderboard. - The remote-database A/B (second table) and the fixes: hearso-ws-game-service PR #10, merged 2026-09-23T16:06Z as
700ae6c5. Its body:b5e4a3bep50 3,658 ms (one run 10,255 ms) against 7 ms, max 20,572 against 21 ms, 22 of 41 unanswered against 0; about 342 ms of database time per 250 ms tick; 2,511 transactions for one game; after the first commit p50 2,702 ms, after both 1,157-1,277 ms with a max of 2,805 ms. PR #11,ad2624f, merged 2026-09-24T00:27Z. (Correction, 2026-09-28: the first version of this post gave "about 230 ms" per tick and "2,702 ms after the partial fix". PR #10's own count is about 342 ms, and 2,702 ms was its first commit alone.) - The deploy of
6ae8af3aand its series: handoff entries 05:30Z and 05:35Z on 2026-09-27 (688 series, 9 histogram families). - TCP connect times (Figure 2, third table):
measure-db-latency.shon the VPS, 2026-09-27 from 03:38:59Z, three runs of ten, each 10 of 10: min/median/max 61/61/62, 62/63/67 and 66/73/82 ms. The 2026-09-22 reading, 10 of 10 with min 59, median 60, max 65: operations notes, 2026-09-22. The 20 ms and 80 ms guide lines are the script's own text. Its comment's "two or three more round trips" for TLS overstated the cost; the post and Figure 2 give one for TLS 1.3 and two for TLS 1.2. - The existing log shipper and the near-miss: overnight handoff, entries 21:10 and 21:15 CDT on 2026-09-26; the deploy kit README's metrics section; the kit's earlier draft, kept as a backup, which wrote the log shipper's config path and filtered its rollback on the service label
alloy. - The pre-deploy checks, the deploy and
up= 1: overnight handoff, entry 21:32 CDT (02:32Z). Collector's first log line at 02:31:25Z;up= 1 at 02:32:36Z; no Alloy errors; build700ae6c5; hearso-rt container unchanged, up 3 days. - Six series, 0 active sessions, one gauge, the round at 02:51Z played with polling: overnight handoff, entry 21:55 CDT.
- What we can see now (fourth table): hearso-ws-game-service PR #17 (merge
0326e143) and PR #18; handoff entries 07:45Z on 2026-09-27 (dashboard, 14 rules) and 00:35Z on 2026-09-28 (17 rules); the 2026-09-28 VPS job, 17:05Z-17:52Z (Kuma, four monitors, the public JSON route; host metrics, 310 series, 13 containers, memory available). - Admin access: handoff entry 21:05 CDT on 2026-09-26 (Tailscale
checkmode); deploys over SSH in the handoff entries of 2026-09-27 05:15Z-05:35Z and 2026-09-28 14:45Z. - hearso-rt logs only to a file: operations notes, 2026-09-22.
- The dial and failover (Figure 3, fifth table): web PR #530 (merged 2026-09-28T18:25:02Z: five presets, guard, 15 s cache, percentages locked until the heartbeat exists) and web PR #531 (19:00:43Z: the heartbeat table, stamped by the database clock); rt PR #22; handoff entries ~18:25Z and ~19:00Z on 2026-09-28 (dial at 0); rt
713c5ef4deployed ~19:25Z with the first heartbeat on PROD (handoff, ~19:25Z entry)./readyalways 200 on loopback: the transport dial design, section 0, fact 3. The first step after the dial: design section 7, decision 12. - The original plan: overnight handoff, entries 22:10 and 22:15 CDT on 2026-09-26.
No credential, token, address of an internal service or player identity appears in this post or its figures.