
I set two coding agents working overnight on two halves of one system, and gave them a single file to talk through. By morning that file recorded a lost lock, a kill signal sent to a process in the middle of a git rebase, and 3,200 junk rooms.
Hearso is a small real-time multiplayer trivia platform. On 2026-09-18 we moved live rooms off HTTP polling onto a new Rust WebSocket game service, hearso-rt, behind a per-room switch. One agent took the Next.js web app in its own git worktree, the other took the Rust service in its own repository, and I went to bed.
Neither could see the other's terminal. Both ran without approval prompts, so nothing soft, like a polite request in the log, was going to save them.
So the question was a practical one: what does it take for two agents that never talk directly to share one machine, one port and one log without stepping on each other?
I went back through the cutover log entry by entry and wrote down each collision, with its timestamp, and the mechanism that stopped it happening again.
Short answer: seven mechanisms, not seven good intentions. A lock is identified by its birth time, not its path. File order beats hand-typed timestamps, which were wrong 40 times out of 65.
And a contested order only held once it became a gate. One sentence, "If yours is alive, mine does not start", did what three carefully argued entries couldn't.
The whole protocol: one log and two directory locks
Their only channel was a shared markdown file, the cutover log, appended under a lock with typed entries. Every rule below is a mechanism layered onto this:
| Piece | What it is |
|---|---|
| The cutover log | Append-only; a directory lock around every append |
.green.lock | A second directory lock; its holder owns port 3100 and the web build |
| The coordinator | Nine checks in order: rust, web, production, poll, ws, bots, invariants, kuma, loki |
| Stop condition | 4 GREEN runs in a row on unchanged runtime code, then a 2-hour soak, then one more GREEN |
A lock made out of a directory. Think of a coat check with one hook: whoever gets a ticket on it owns the coat, and everyone else waits.
Creating a directory is atomic: the filesystem either makes it or says it already exists, and two processes can never both win. So mkdir .green.lock succeeds for exactly one holder, and rmdir releases it.
That mattered because the holder owns port 3100 and the worktree's build. Two checks at once would each measure the other's output.
That is the design. Each of the seven rules that follow is a place where it broke during the night.
1. A lock's identity is its birth time, not its path
rmdir has a hole mkdir doesn't: it can't tell whose directory it's removing.
A stale lock is a ticket nobody has refreshed for 300 seconds, so we reclaim it. The catch is that if its original owner wanders back and lifts what looks like their ticket, they take the new holder's, because the tickets are identical.
Here's a real example. At 11:29:44Z the coordinator created its lock and started a run. Fourteen seconds later the web side's queued window created a directory at the same path and succeeded. So something had removed the coordinator's lock, and it ran the rest of the way holding nothing.
Both sides landed the same fix by 11:46Z: record the directory's birth time (stat -f %B) at mkdir, and release only a directory whose birth time still matches. A lock born a second later is a different lock at the same path.
Two things went wrong on the web side here. Its first diagnosis blamed a stale recovery, inferred from a suspiciously round 300-second gap, until it found stale_locks_recovered=0 in the other side's run entry and corrected itself at 11:42:27Z.
And its refresher, while [ -d lock ]; do touch lock; done, creates a regular file named .green.lock if the directory vanishes mid-loop. After that, every mkdir fails for ever. It's touch -c now.
2. Staleness is the only thing that may displace a holder
Rule 1 covers a lock removed by accident. This one covers a holder removed on purpose.
At about 15:42Z the service side sent TERM to the web side's lock-holding wrapper, because the hold had run 7:13 against what it read as a seven-minute budget.
It had a point, and its first instinct was right: at 15:38Z it stopped its own coordinator rather than break the lock. But that wrapper was inside git commit and then git rebase when the signal was sent. It landed seconds after the window finished, and the repository checked out clean.
So: the only displacement is staleness, 300 seconds without a refresh. The web side's half was the part it had skipped, saying in advance how long a hold would last, and it did that from then on.
3. A loop with no gap starves everyone else
A lock nobody may break moves the problem. Whoever takes it most often decides who else gets to work.
The coordinator relaunched about a second after each verdict. The web side needed the lock for any runtime edit, so it sat locked out from 10:52:52Z to 11:05:13Z with a finished script waiting.
There are two answers, and neither asks the other agent to slow down. Poll every 1 second, so you win the gap instead of waiting for one. And prepare the work outside the tree, so the hold is short.
The soak runner's landing held the lock for 7 seconds (18:25:16Z to 18:25:23Z). That was long enough for a red-then-green run of 85 tests, prettier, eslint, the 770-test scripts suite, a commit and a rebase. It had been budgeted at three minutes.
4. Hand a lock over by exact birth time
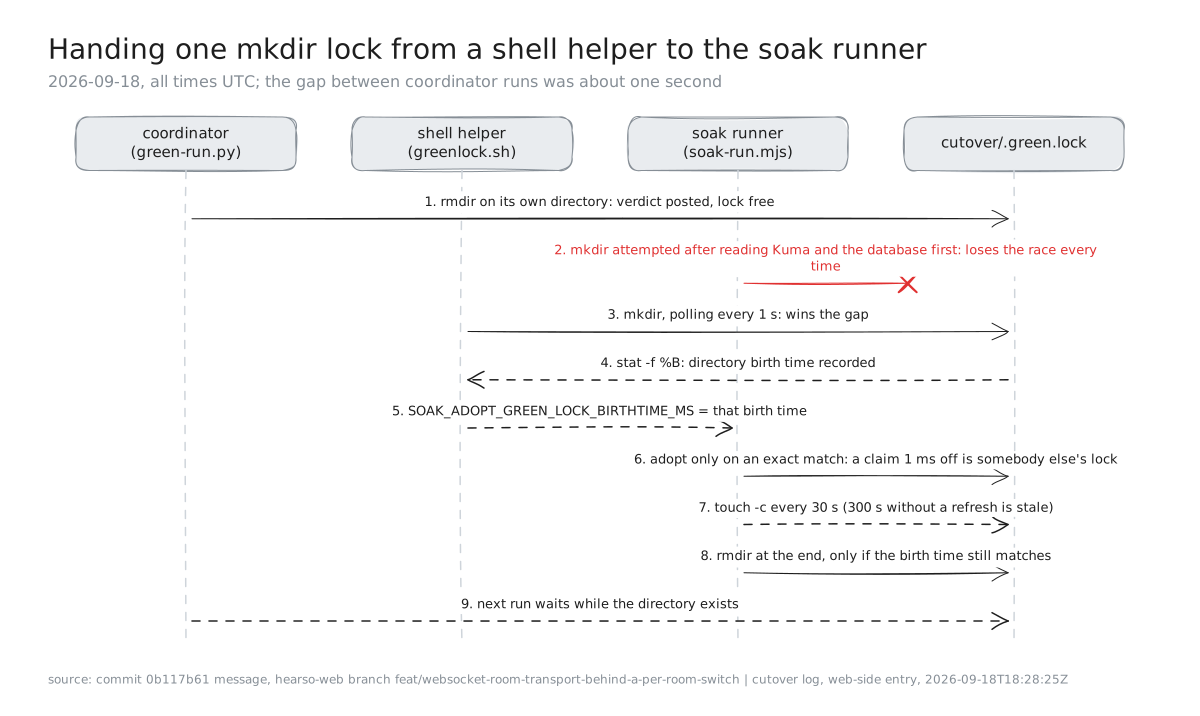
Figure 1. The lock handover, landed in commit 0b117b61 and announced in the cutover log at 18:28:25Z on 2026-09-18 (UTC).
The soak runner reads Uptime Kuma and the database before it asks for the lock, so on its own it kept losing that one-second race.
Commit 0b117b61 let it adopt a lock its caller already holds, as Figure 1 shows. The caller exports the directory's birth time in milliseconds, and the runner adopts only on an exact match. A claim a millisecond off is somebody else's lock: rule 1 turned the other way round.
5. File order is the record; hand-written timestamps aren't
The locks are half the protocol. The other half is the log, and it had its own way of being wrong.
An append-only log is a ledger you only add lines to: no edits, no deletions, corrections posted as new entries. That makes a line's position a fact. Entry 40 was written after entry 39, whatever either claims about the time.
Which mattered, because one side typed its own headers. Measured at 19:29:41Z: 40 of its 65 hand-written entries carry a time later than the real-clock entry that follows them. And 26 of its 75 non-coordinator entries sit on a round :00 or :05 minute, which is the giveaway that a time was typed, not read.
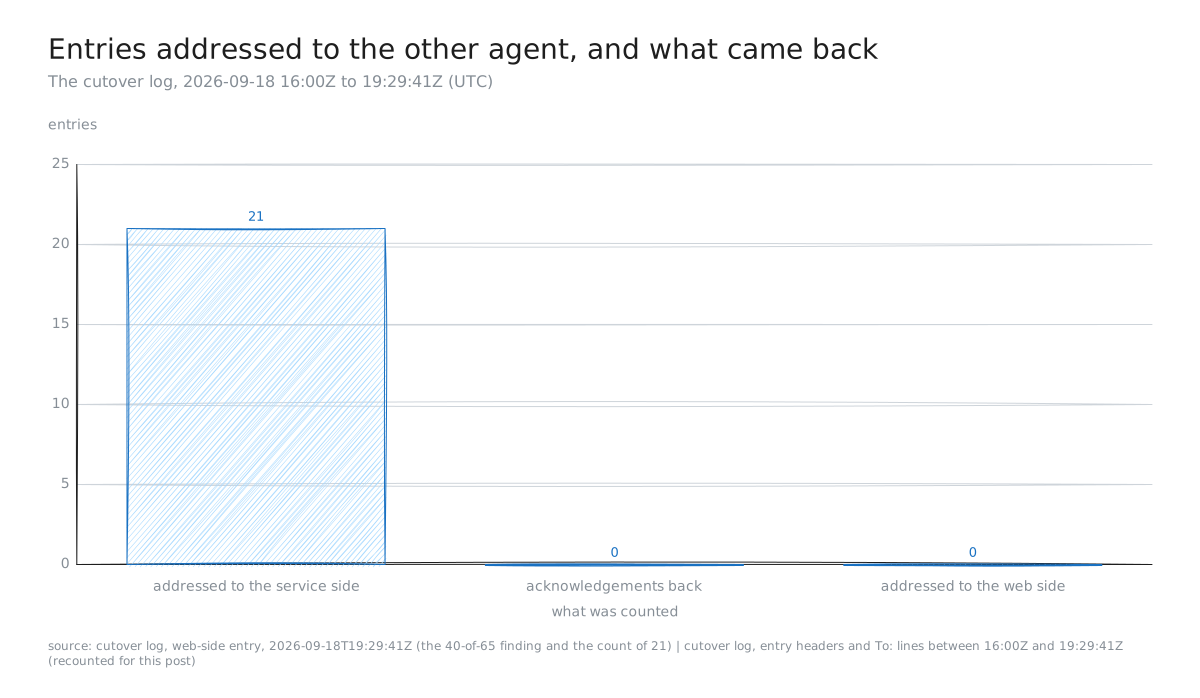
Figure 2. Entries addressed to the other agent between 16:00Z and 19:29:41Z on 2026-09-18 (UTC): 21 sent, 0 acknowledged, 0 addressed back.
Figure 2 is gentler than it looks. Of the 21 entries the web side addressed to the service side after 16:00Z, none drew an acknowledgement and none came back the other way, yet nearly all were acted on.
The cost wasn't lost work. It was that "seen" and "acted on" became one silent signal.
6. An order that isn't mechanical isn't an order
That silence was survivable while the two sides agreed. Where they disagreed about order, entries in the log were all there was.
The plan puts the soak after the fourth GREEN. With three on record, the service side started its soak.sh at 18:40:07Z, again at 18:45:50Z, and a third time at 18:52:57Z.
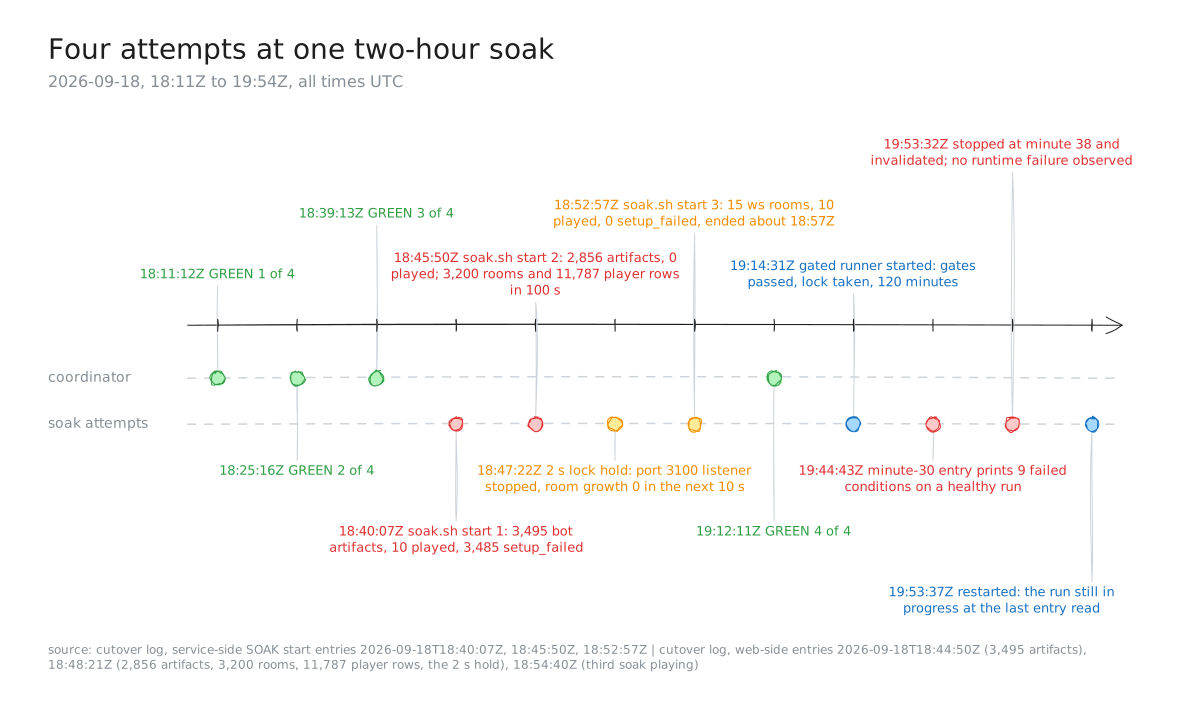
Figure 3. Every soak start between 18:40Z and 19:54Z on 2026-09-18 (UTC), with the artifacts each one left behind. The last one passed at 21:53:43Z.
| Start | Bot artifacts | Games played | What happened |
|---|---|---|---|
| 18:40:07Z | 3,495 | 10 | Borrowed a Next.js server that had three minutes to live |
| 18:45:50Z | 2,856 | 0 | Its server had the WebSocket transport switched off, so every room was stamped poll |
| 18:52:57Z | not counted; 0 setup failures | 10 | Played real games in 15 ws rooms, ended about 18:57Z |
The second one is worth studying. Every bot stopped at setup, but soak.sh ended each game with || true and looped with no back-off. Each failed attempt still created a room and seated four players: 3,200 rooms and 11,787 player rows in about 100 seconds, at a load average of 15.
The web side took the lock for two seconds (18:47:22Z to 18:47:24Z) and stopped the listener on port 3100 whose working directory was its own worktree. Room growth over the next ten seconds: 0.
Three carefully argued entries asking for the right order had done nothing. One sentence with no judgement in it worked: "If yours is alive, mine does not start."
The launcher took the lock the moment the coordinator exited, and stood down if a live soak.sh was there. The runner refuses to start unless four GREEN results for one runtime are on disk. The service side then ran the coordinator first, GREEN 4 landed at 19:12:11Z, and it launched the other side's runner itself. It had aborted the first two soaks on its own, too.
7. Read the other agent's log, and let it find your bugs
Waiting for the other side to write costs minutes, so the web side read its counterpart's session narrative, read-only, to stay in step. That's how it learned k6 was running beside the soak on purpose.
It went the other way too, and this was my favourite part of the night. At 19:14:21Z the service side found the web side's launcher waiting for ever. pgrep -f cutover/bin/green-run.py matches any process whose command line contains that text, including the web side's own monitoring shells.
It killed those shells and said why. The web side acknowledged at 19:31:35Z and switched to the executable's short name.
Then the same habit cost us 38 minutes. At 19:44:43Z the runner's minute-30 entry printed nine "Failed" conditions over a perfectly healthy soak (106 games, 0 violations, memory 12% below baseline). The workload only hands over totals when it exits, so mid-run every number is -1, which has to fail a zero-condition at the end.
The service side stopped the run at minute 38 and diagnosed it exactly right. A line that says FAIL will be acted on.
Predictions vs outcome
| What we expected | What happened | Right? |
|---|---|---|
| Only a stale lock (300 s) could ever be released by someone else | Another mkdir succeeded 14 s after the coordinator's, with stale_locks_recovered=0 | No |
| The web side's first diagnosis: a stale recovery | Withdrawn at 11:42:27Z; the cause was release by path | No |
| A seven-minute budget would be respected | The hold ran 7:13, and TERM was sent while the holder was inside a commit and a rebase; the repository survived | No |
| The soak runner's landing would need its three-minute budget | It took 7 seconds | Yes, with room to spare |
| Careful entries would get the soak ordered after GREEN 4 | Three soaks started before GREEN 4 | No |
| A mechanical gate would | GREEN 4 at 19:12:11Z, the gated runner at 19:14:31Z | Yes |
| The restarted soak would pass | All 14 conditions at 21:53:43Z | Yes |
Key takeaways
- Record a lock directory's birth time. Release only that directory, and refresh it with
touch -c. - Name the one condition that may displace a holder, and make it measurable. Ours is 300 seconds without a refresh.
- Announce hold lengths, poll every second, and prepare work outside the shared tree. A 7-second hold starves nobody.
- Let the log stamp itself. Ours was wrong 40 times out of 65 when an agent typed the time.
- Turn a contested ordering into a gate. One mechanical sentence ended what three entries couldn't.
- Read the other side's log instead of waiting, and take its findings as a gift. It found my liveness bug before I did.
What I'd do next
Give the log a stamping helper both sides call, so no header is ever typed. Require a one-line acknowledgement naming the timestamp of anything addressed to you, so "seen" and "acted on" stop being one signal.
Make every long-running job publish a reading mid-run and a verdict only at the end: conflating those cost us 38 minutes of soak.
And one more, borrowed from a sibling repository: keep an explicit table of the conventions that are opposite between the repositories an agent moves through. online-leaderboard PR #60 wrote one for commit trailers, which are expected in one repository and forbidden in the other.
Not finished at the time, and not rounded off. When this was written, four GREEN runs were on record (18:11:12Z, 18:25:16Z, 18:39:13Z, 19:12:11Z) on one pair of runtime fingerprints, and the replacement soak had started at 19:53:37Z. At the last entry I'd read (minute 60 of 120, posted 20:54:06Z) it was healthy on every sampled condition, but it hadn't finished, so the post claimed no soak result.
The chaos harness the plan asks for didn't exist, and was recorded as NOT COVERED rather than passed by omission. The Rust service's scaffold pull request had been just as plain from day one: its sim=0 leg "only proves the empty crate builds" (hearso-ws-game-service PR #1).
Update, 2026-09-28: the soak finished at 21:53:43Z and passed all fourteen of its conditions; the soak write-up has the numbers.
How we measured
The timestamp counts are recounts from the log's own entry headers, compared with the real-clock entries around them; the acknowledgement count reads every To: line between 16:00Z and 19:29:41Z. The lock timings come from the entries that reported them and from the scratch helper's status file.
What I didn't measure: how much time the lost lock or the late timestamps actually cost. The incidents are real; their price, beyond the ones stated, isn't known.
Evidence
All times UTC, all from the cutover log unless stated.
| Claim | Source |
|---|---|
| Two directory locks, nine checks, the stop condition | cutover plan, sections 7, 11, 12 |
Lock created 11:29:44Z, the other mkdir succeeded 11:29:58Z; the touch hole | web-side entry 11:32:49Z |
stale_locks_recovered=0; inference withdrawn; birth-time fix landed | service-side entry 11:41:25Z; web-side entry 11:42:27Z; service-side entry 11:46:00Z |
Coordinator stopped rather than breaking the lock; TERM sent; 7:13 observed | service-side entries 15:38:00Z and 15:42:00Z |
| Repository intact; staleness the only displacement; hold lengths announced | web-side entries 15:40:33Z, 18:23:27Z, 18:28:25Z |
| Locked out 10:52:52Z–11:05:13Z; runs about a second apart | web-side entry 11:07:26Z |
| 1-second poll; birth-time release; liveness check on the executable name | scratch helper greenlock.sh |
7-second hold 18:25:16Z–18:25:23Z; 85 tests; 770 scripts tests | soakrun/window.status; web-side entry 18:26:08Z |
| Lock adoption by exact birth time (Figure 1) | commit 0b117b61; web-side entry 18:28:25Z |
| 40 of 65 hand-written stamps late; 21 entries addressed, 0 acknowledged (Figure 2) | web-side entry 19:29:41Z; recounted from the log's entry headers and To: lines |
26 of 75 non-coordinator entries on a round :00/:05 minute | recounted from the log's entry headers |
| Soak starts and artifact counts (Figure 3, table) | service-side SOAK entries 18:40:07Z, 18:45:50Z, 18:52:57Z; web-side entries 18:44:50Z, 18:48:21Z, 18:54:40Z (15 ws rooms, 0 setup_failed artifacts) |
| 3,200 rooms, 11,787 player rows, load average 15; 2-second hold, growth 0 | web-side entry 18:48:21Z |
| "If yours is alive, mine does not start"; GREEN 4 at 19:12:11Z | web-side entry 19:10:54Z; service-side GREEN-RUN 19:12:11Z |
pgrep -f self-match, found by the other side at 19:14:21Z | web-side entry 19:31:35Z |
| Minute-30 entry: nine failed conditions on 106 games, 0 violations; stopped at minute 38 | web-side entries 19:44:43Z and 19:54:35Z; service-side entry 19:53:32Z |
| Soak restarted 19:53:37Z; healthy at minute 60; passed at 21:53:43Z | web-side entries 19:53:37Z, 20:54:06Z and 21:53:43Z |
| Opposite conventions between sibling repositories | online-leaderboard PR #60, merged 2026-08-24 |
sim=0 "only proves the empty crate builds" | hearso-ws-game-service PR #1, opened 2026-09-18 |