
Reading the top 25 of our leaderboard is one query with no sorting anywhere, because the sort key stores every score inverted.
Hearso is a real-time trivia game. Rounds end together, so scores arrive in bursts, and every player wants to see where they landed before the next question loads. We built the leaderboard on DynamoDB behind AWS SAM and Lambda, because "give me the top 25 of this board" is exactly the read a sorted index is good at, and because we did not want to run a database.
The catch is one AWS states in its own leaderboard comparison: DynamoDB can hand you the top N, but not "player X is ranked 4,327th". No design of ours changes that.
So the question was whether one table design could make "who's on top" free and "where am I" affordable, without adding a second datastore.
The design landed on 2026-08-11. On 2026-08-18 we measured how long a score takes to become readable, on DEV, across boards of 100 to 10,000 players (300 samples). The next day we pushed 1,000 new players at one board. Histogram counters arrived on 2026-08-18 and player erasure on 2026-09-04.
Short answer: the top of a board is a plain ascending read. A submitted score was readable in 159 ms at p50 and 210 ms at p95, flat from 100 to 10,000 players, against a 1-second target. Deep rank costs at most 2,000 index entries plus one item and comes back as a range. The weak spot is one counter row per board. When we pushed 1,000 new players at one board, 475 failed at 64 in flight, and our first explanation for that was wrong.
This post is the whole table design, the reasoning from AWS's own papers and docs behind each choice, and an honest split of which numbers are measured, which are arithmetic, and which don't exist yet.
Where an item lives decides what a read costs
Three ideas carry the whole design. Figure 1 draws the first two at once.
The address and the shelf. Think of a coat check: your ticket number decides which room your coat hangs in, and within that room the coats hang in order along a rail.
Precisely, the partition key is fed to a hash function whose output picks the physical storage, and the sort key decides the item's position among everything sharing that partition key. AWS states the consequence plainly: "All items with the same partition key value are stored together, in sorted order by sort key value."
Our leaderboard index is partitioned by a board id like trivia#alltopics#alltime and sorted by a string we build per player. That is the whole trick: if items are stored in sort-key order, "the top of the board" is "the first items", and there is nothing left to sort.
The partition and its ceiling. A partition is a shelf with a weight limit; overload one shelf and the shelf fails, not the warehouse. Precisely, it is SSD-backed storage replicated across Availability Zones holding "a disjoint and contiguous part of the table's key-range". Its ceiling is documented: "Each physical partition can support 3,000 read units per second and 1,000 write units per second."
Our largest benchmarked board held 10,100 rows, so we are nowhere near that. It still shapes the design, because one board is one partition key. If a board gets popular, that is where it shows.
The index is always slightly behind. A global secondary index is a second copy of your data filed under a different key, maintained for you but not synchronously: "any global secondary indexes on that table are updated asynchronously, using an eventually consistent model". You cannot opt out: "Queries on global secondary indexes support eventual consistency only." So a successful write and a readable ranked entry are two different moments, which is why we measured the gap rather than wishing it away.
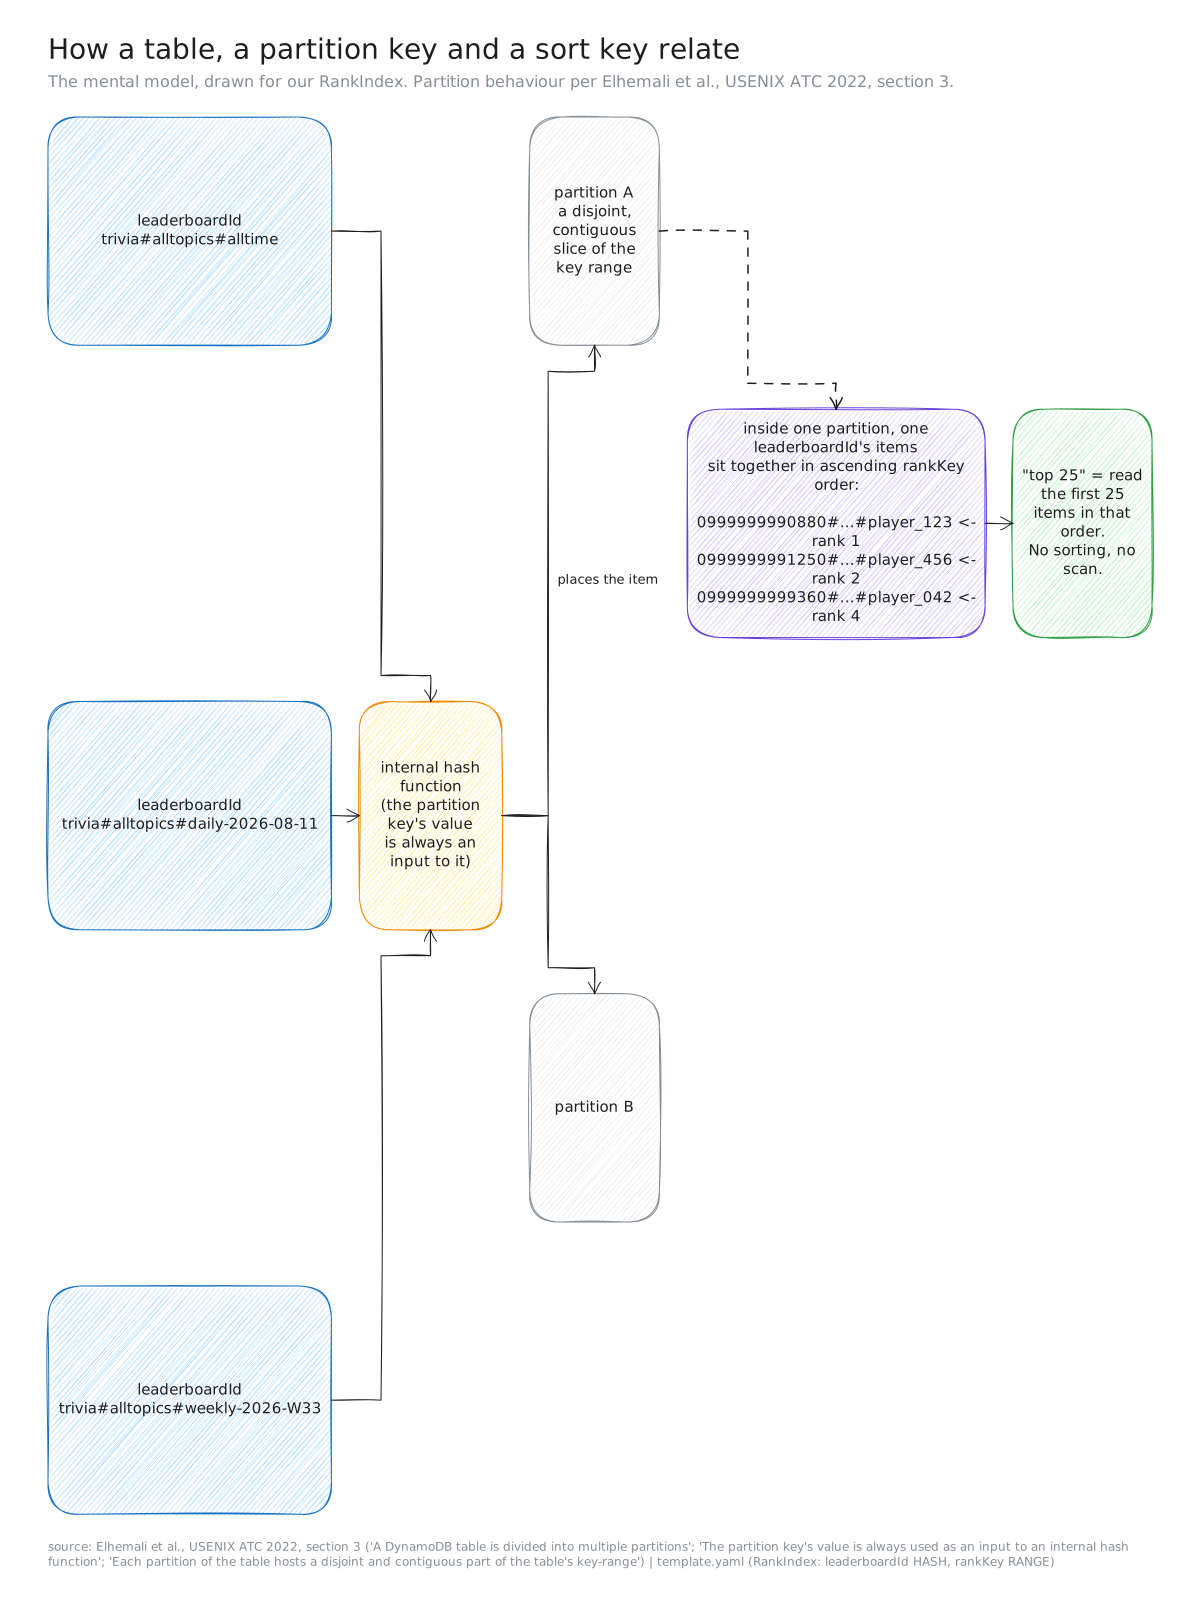
Figure 1. The two jobs a composite primary key does, drawn for our RankIndex. Partition behaviour per Elhemali et al., USENIX ATC 2022, section 3.
A note on the name. DynamoDB shares "most of the name of the previous Dynamo system but little of its architecture". What carried over is a value: Dynamo's authors measured service levels "at the 99.9th percentile of the distribution" rather than the mean. Our target is a p95 for the same reason.
Two tables, one index, no streams
Here are our tables exactly as configured.
| Scores table | Snapshots table | |
|---|---|---|
| Partition key | playerId | leaderboardId |
| Sort key | leaderboardId | snapshotTakenAt |
| Indexes | one GSI, RankIndex | none |
| Billing mode | PAY_PER_REQUEST | PAY_PER_REQUEST |
| TTL | on expiresAt | none, on purpose |
| Point-in-time recovery | enabled | enabled |
| Encryption | AWS-owned key (the free default) | AWS-owned key |
| Streams | none | none |
| Protection | deletion protection, plus Retain on stack delete and replace | same |
RankIndex is keyed leaderboardId / rankKey and projects three extra attributes: displayName, country, lastPlayedAt.
The base table is keyed the other way round on purpose. A player's standings across every board, variant and period is one query on playerId. That is what makes GDPR erasure a query rather than a scan.
Why is the score stored backwards?
Imagine a filing cabinet that only hands you folders front to back. If you want the best score first, you have to file it at the front.
The sort key is a string compared byte by byte, ascending by default. So we store the inverted score, SCORE_CEILING − score, zero-padded, and an ordinary ascending read becomes a descending leaderboard. SCORE_CEILING is 10^12 and the pad width is 13 digits, which is exactly enough: at score 0 the inverted value is 1,000,000,000,000.
The full key is <invertedScore(13)>#<achievedAtMillis(13)>#<playerId>. Here's a real example from the shipped key builder, with four made-up players on one board, in the order DynamoDB stores them:
0999999990880#1786458127000#player_123   score 9,120
0999999991250#1786458127000#player_456   score 8,750, achieved 14:22:07Z
0999999991250#1786458131000#player_789   score 8,750, achieved 14:22:11Z
0999999999360#1786458127000#player_042   score 640
That is a plain ascending string sort. Reading the top 25 is one Query with ScanIndexForward: true and Limit: 25. Figure 2 shows those four keys as the index holds them.
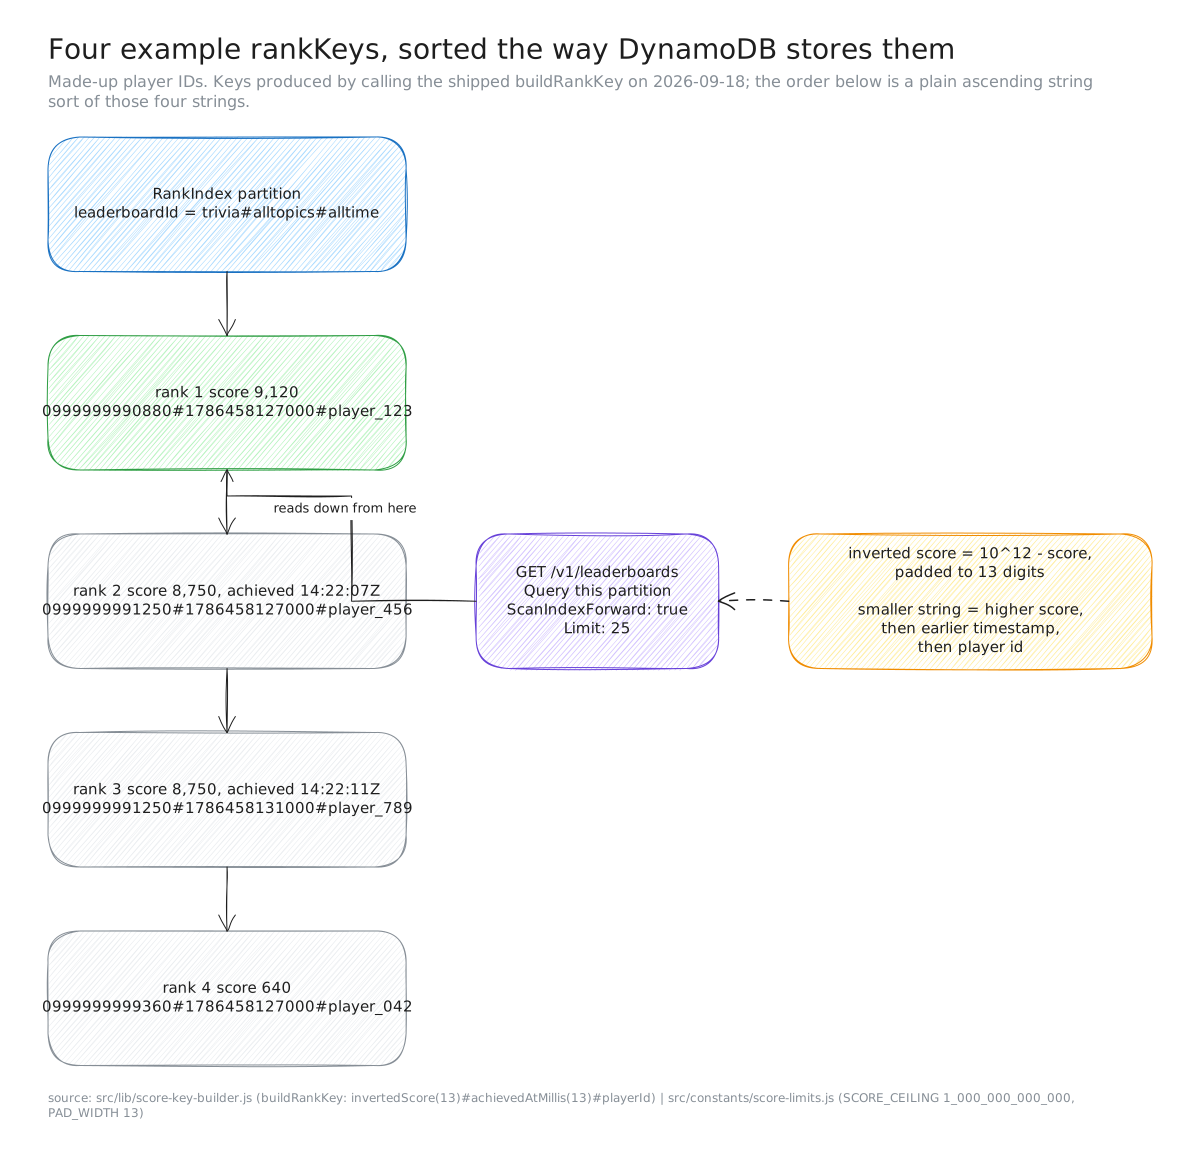
Figure 2. Example rankKey values for four invented players, in the order DynamoDB stores them. Computed from the shipped key builder on 2026-09-18; no player data here is real.
Why not just read the index backwards?
Here is the part I did not see coming. DynamoDB can already read a sort key backwards: "set the ScanIndexForward parameter to false". So inverting looks redundant.
It is not, because our tie-break runs the other way. We want the highest score first, then the earliest achievement. Read descending and the timestamps come back latest-first, which crowns the wrong winner.
By inverting only the score, "highest score" and "earliest achievement" both become "smallest string". One ascending read satisfies both rules with no comparison logic downstream. Delimiter-joined sort keys are a documented AWS pattern, not our invention: the guide's own example is [country]#[region]#[state]#[county]#[city]#[neighborhood].
One guard rail sits under this. A score at or above the ceiling would produce a negative inverted value whose - sorts before 0, silently corrupting the board's order. The key builder throws instead.
Three index decisions, and the one I got half wrong
Global, not local. A local secondary index shares the base table's partition key, so ours would have been partitioned by playerId: answering a question nobody asked. Two more differences confirmed it. An LSI caps indexed items at 10 GB per partition key value, and "You cannot add a local secondary index to an existing table, nor can you delete any local secondary indexes that currently exist."
AWS's own gaming write-up reaches the same shape from the other direction: "The index would use the game ID or name as the partition key, and the top-score attribute as the sort key." That post scopes the claim to simple leaderboards, and it is right to.
The projection, where I was wrong. A projection is the set of attributes copied into the index. We chose INCLUDE with three fields so a 25-row page needs no follow-up fetch. Re-reading the guidance, I found our recorded reasoning half wrong. ADR-0010 justified INCLUDE partly on write cost, but the docs say projecting fewer attributes only reduces write cost if those attributes would otherwise exceed 1 KB: "As long as the index items are small, you can project more attributes at no extra cost."
Our entries are far under 1 KB. So the choice saves storage and keeps a free-form context map out of the index, and probably saves no write capacity at all.
What an indexed key does cost is sharper than I expected: "If an update to the table changes the value of an indexed key attribute (from A to B), two writes are required, one to delete the previous item from the index and another write to put the new item into the index." Every improvement changes rankKey, so it costs two index writes, not one.
Rows that never reach the index. The Scores table also holds idempotency records under an idem# prefix, one counter row per board under meta#, and seeding leases under seedlock#. None carries a rankKey, and that omission alone keeps them out of the index: "DynamoDB writes a corresponding index entry only if the index key attributes are present in the item."
An index holding only some of a table's items is a sparse index, and global indexes are sparse by default. We got the behaviour by not writing an attribute.
One submission is up to 8 table writes and 6 index writes
Everything so far made the read cheap. The price of that is paid on the write, and this section counts it.
Per board, a submission reads the player's row with ConsistentRead: true, commits one transaction, then optionally counts. The transaction holds three items (a condition check on the board's seeding lease, the score-row update, and the counter update) and is all-or-nothing. The score update is conditional on exactly the state that was read. So a concurrent winner cancels it, and the handler re-reads and retries: three attempts with jittered backoff when this was written, eight since (see the update further down).
An idempotency record wraps the request. A PutItem conditional on attribute_not_exists reserves the key before any board is touched. The outcome is stored after, so a retry replays the original response rather than re-running the fan-out. By default a submission fans out to three boards: all-time, the UTC day, the ISO week.
There is no DynamoDB stream here, and no stream consumer. Neither table declares a StreamSpecification, and the template has no event source mappings. The reconciler is an offline tool that reads a board twice from the index and compares before it repairs anything. I say this plainly because a streams-based fan-out is the obvious architecture, and it is not the one we have. Figure 3 has the full order.
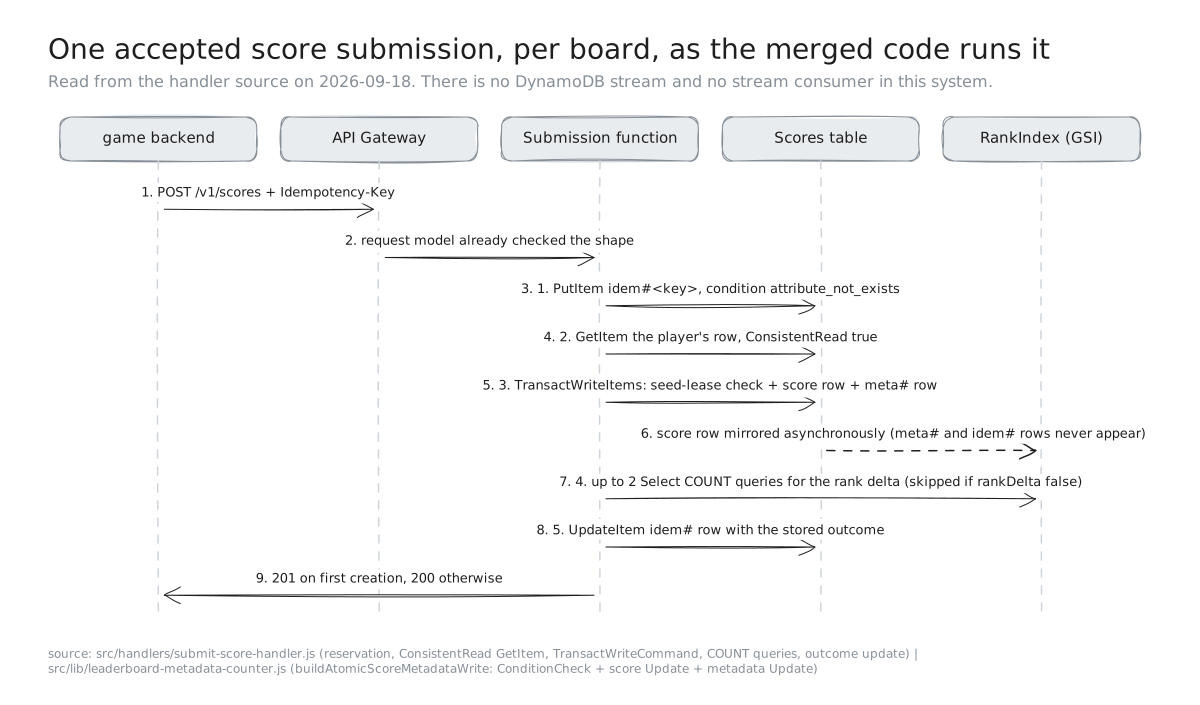
Figure 3. The write choreography for one board, in the order the merged handler issues it. Read from source on 2026-09-18.
Counting the writes is arithmetic, not measurement, but it is arithmetic over verified code and AWS's documented index rules:
| What the score did | Writes on Scores | Writes in RankIndex |
|---|---|---|
| New player, three boards | 8 | 3 |
| Improved, crossing a bucket | 8 | 6 |
| Improved, same bucket | 5 | 6 |
| No improvement | 5 | 3 |
The Scores column is one reservation, three score-row writes, up to three counter writes and one outcome write. Figure 4 puts the two columns side by side.
For contrast, ADR-0009 priced this at nine conditional writes, assuming three variants that still do not exist. Neither number is wrong; they answer different questions, five weeks apart. The companion post on the write fan-out follows that estimate in detail.
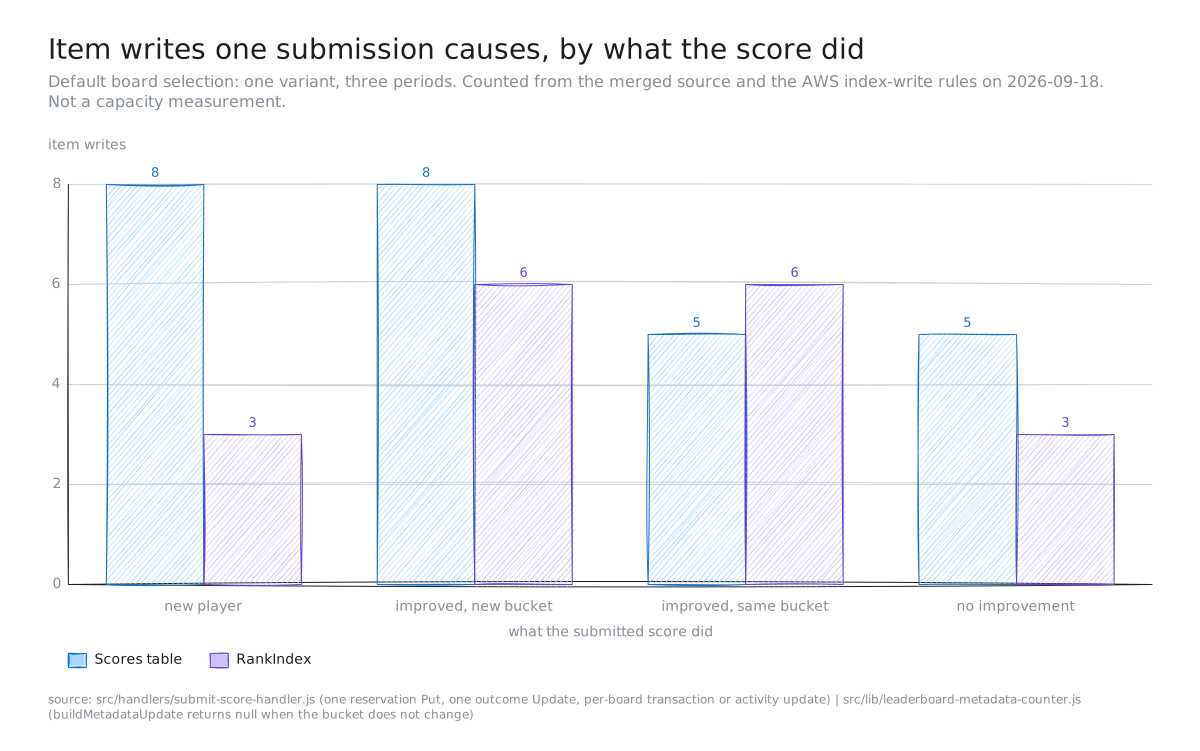
Figure 4. Item writes per accepted submission with the default three-board fan-out, counted from source on 2026-09-18. Item counts, not billed capacity units.
A leaderboard page is two calls, both eventually consistent
GET /v1/leaderboards issues two calls at once: the index query, and a GetItem on the board's meta# row for the player-count denominator. Both are eventually consistent, which is all a display count needs.
ScanIndexForward: true is stated explicitly even though it is the default, because it is the read path's central claim rather than an accident. Ranks are stamped from each row's position in the page. The score is decoded back out of the rankKey; the projection omits it deliberately, because the inverted key already carries it.
LastEvaluatedKey becomes the next ExclusiveStartKey, wrapped in an opaque cursor that carries the rank the next page starts at.
Deep rank is where DynamoDB stops helping
AWS says so itself. In its leaderboard comparison, the cons listed under DynamoDB are "No built-in rank computation" and "You can get top-N but not 'player X is ranked 4,327th' efficiently". There is no order-statistic operation, and Select: COUNT reduces bytes returned, not entries read.
So we cap it. A bounded query counts at most 2,000 entries; under that, rank is exactly count + 1. Past the cap we fall back to a histogram: 128 counters held as top-level attributes bucket000 to bucket127 on the board's meta# row, updated in the same transaction as the score.
Assignment is logarithmic, min(127, floor(ln(1 + score) / ln(10^12) × 128)), which puts the resolution where ordinary trivia scores live:
| score | bucket |
|---|---|
| 0 | 0 |
| 10 | 11 |
| 100 | 21 |
| 1,000 | 32 |
| 8,750 | 42 |
| 9,999 | 42 |
| 1,000,000 | 64 |
| 999,999,999,999 | 127 |
Scores from 0 to 9,999 occupy buckets 0 through 42 and touch 40 distinct buckets; bucket 42 spans scores 8,659 to 10,745. Those are computed from the shipped function, not measured. Summing the buckets above yours gives a rank range. The response returns rank: null with both a rank range and a percentile range, so an approximation is never dressed up as a fact.
Two honest limits. The histogram bounds the read cost of a deep estimate: at most 2,000 index entries plus one fixed-size item, whether the board holds a hundred players or a million. It does not spread writes, and there is no bucket prefix in the sort key; an earlier draft of ours got that wrong. And it cannot see ordering inside a bucket, so the range deliberately contains every tied position that could be correct.
The histogram has its own post.
A score is readable in 159 ms, at every board size we tried
On 2026-08-18, against DEV in us-east-1 with response caching off, we measured the time from a successful POST /v1/scores to that player being readable through GET /v1/leaderboards.
| Board size | p50 | p95 | p99 |
|---|---|---|---|
| 100 players | 160 ms | 235 ms | 449 ms |
| 1,000 players | 158 ms | 181 ms | 206 ms |
| 10,000 players | 158 ms | 210 ms | 265 ms |
That is 300 samples, 100 per size, with zero errors. Run-wide: p50 159 ms, p95 210 ms, p99 322 ms, against a target of 1 second at p95. An earlier run the same day, on two board sizes only, gave 162 / 239 / 338 ms; that is the run ADR-0012 set the target from. (Why we rejected that run is a story of its own.)
The flatness is the interesting part, and Figure 5 plots it against the target. Propagation did not degrade as the board grew a hundredfold. That fits AWS's documented expectation that index changes propagate "within a fraction of a second, under normal conditions".
Most of our 159 ms is probably API Gateway, Lambda and network rather than index lag. We did not measure the split, so treat that as a guess.
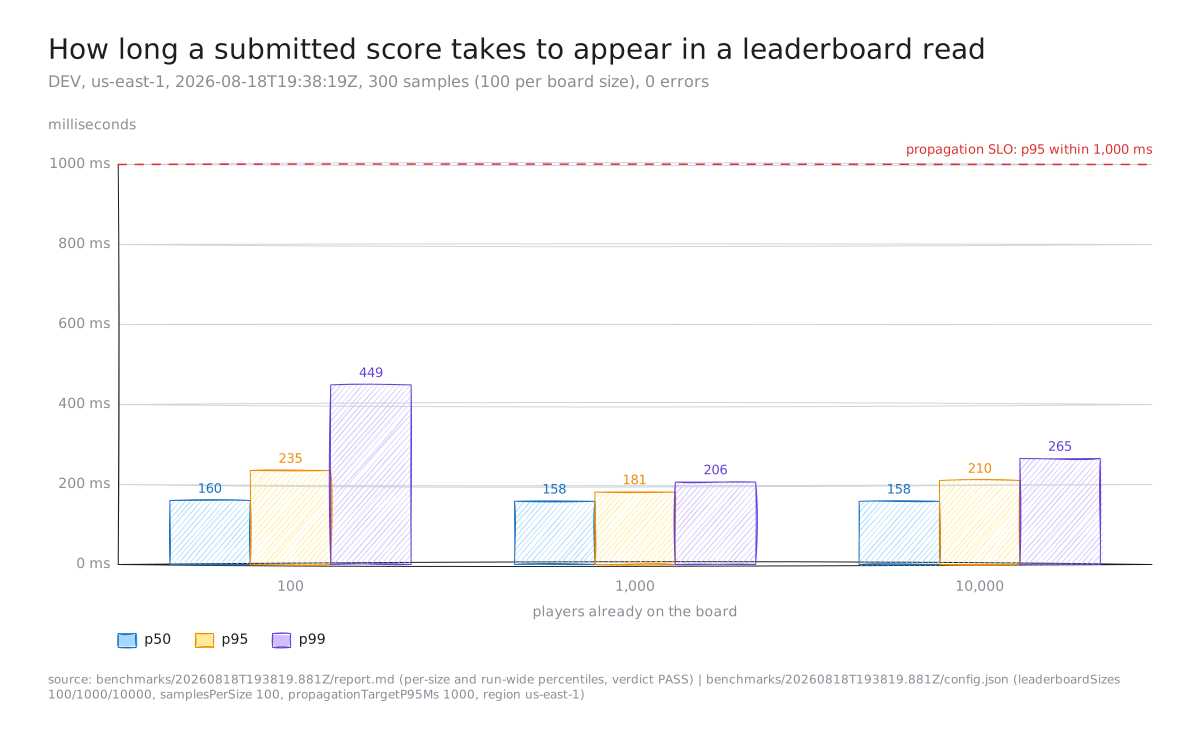
Figure 5. Measured propagation per board size, DEV us-east-1, 2026-08-18T19:38:19Z, 300 samples, 0 errors, against the 1,000 ms p95 target.
1,000 new players on one board, and a failure we explained wrongly at first
The second measurement is less flattering and more useful. On 2026-08-19 we drove 1,000 new players onto a single board:
| In flight at once | Succeeded | Failed |
|---|---|---|
| 8 | 1,000 | 0 |
| 16 | 986 | 14 |
| 64 | 525 | 475 |
| 1,000 | 204 | 796 |
DynamoDB reported zero throttled requests throughout. At the clean level the table consumed 6,868 write capacity units in the peak minute.
The run's decision note reads the binding limit as transaction conflict on the board's single meta# counter row, which every new player must update, not capacity. That is a reasonable reading. It also turned out to be wrong.
Update, 2026-09-28: it was the Lambda limit, not the counter row. The run recorded no failure reason per request, but CloudWatch keeps five-minute metrics for 63 days, longer than the logs. In them, Lambda concurrency sat pinned at exactly 10 while Lambda throttled 2,471 invocations. The API returned 2,562 server errors in the whole run, so at most 91 had any other cause. DynamoDB gives the same 91 on its own: 2,806 idempotency reservations, 2,715 committed transactions.
Conflicts were real, 1,177 of them, but the handler's retries absorbed all but those 91 at most. The one gap is the 16 level. It shared a five-minute bucket with the 64 level, so its 14 failures are consistent with throttles but can't be attributed request by request: that bucket's 65 handler failures could cover all 14.
We re-ran the same ladder on 2026-09-28 with a reason recorded on every request, against today's code (eight attempts per conflict, not three) and today's limits. At 16 in flight, conflict failed 1 request in 1,000. At 64 it failed 50, beside 216 Lambda throttles at the function's new cap of 50 and 428 refusals from the API key's usage plan. Conflict is the next limit, not the one we hit in August.
What does it cost? Arithmetic, not a bill
Both tables are PAY_PER_REQUEST. Our traffic is spiky by design: a seeding run dumps hundreds of writes in seconds, then the table sits quiet for hours. Provisioning for the spike wastes money all day; provisioning for the quiet throttles the spike.
AWS calls on-demand "the default and recommended throughput option for most DynamoDB workloads". A new on-demand table already sustains "up to 4,000 writes per second and 12,000 reads per second".
The write arithmetic, with its assumptions: 1,000 accepted submissions a day, all from new players (the worst case), the default three boards, every item under 1 KB. A standard write is 1 write request unit per 1 KB. A transactional write is 2, because DynamoDB "performs two underlying reads or writes of every item in the transaction: one to prepare the transaction and one to commit".
- Reservation and outcome: 2 units
- Three boards × two transactional items × 2: 12 units
- Three index entries: 3 units
- About 17 write request units per submission, so roughly 510,000 a month
At the rate printed in AWS's own pricing worked example for US East (N. Virginia), $0.6250 per million writes, that is about $0.32 a month in write requests.
That number is thinner than it looks. It excludes reads, storage, the transaction's condition-check item, and any month where players improve rather than arrive. The rate comes from a worked example embedded in the pricing page; the headline rate table renders in the browser and would not load for us. Treat it as one Region on one date, not a quote.
And nothing has ever been billed: the production stack did not exist when this was written.
Update, 2026-09-28: the production stack was created on 2026-09-26. Nothing in this post has been measured against it.
The read cost is what I would watch first, and it is not in that sum. Two Select: COUNT queries run per board when a client wants its rank delta at submit time. A COUNT still reads every entry it counts, so on a large board those dominate the request. That is why rankDelta: false exists on the contract.
What could hurt us, according to the theory
So far this post has asked what the design does well. This section asks the opposite: where would it break first?
A hot partition on one popular board. One board is one partition key, so all its index traffic lands in one place, against that 3,000 read / 1,000 write per second ceiling. AWS remediates automatically: split for heat "might split the partition into two new partitions" at no extra cost.
The classic manual fix is write sharding, and I am wary of it, because its documented tax lands on our best feature: "to read all the items for a given day, you would have to query the items for all the suffixes and then merge the results." One already-sorted query is the point; sharding turns it into N queries and a merge.
The hot metadata row. A single item cannot be split out of trouble: "a partition receiving high traffic to a single item … will not benefit from split". Adaptive capacity's best offer is to isolate it and hand it "the partition maximum of 3,000 RCUs and 1,000 WCUs".
Our failures above eight in flight appeared long before any of that. The run attributed them to serialised transactions on one row; as above, they were mostly Lambda throttles at a concurrency limit of 10, and the 14 at the 16 level are consistent with that but cannot be attributed one by one. We set a review trigger rather than sharding pre-emptively, and conflict is now the limit that trigger watches.
Index back-pressure. The docs warn that "If you perform heavy write activity on the table, but a global secondary index on that table has insufficient write capacity, the write activity on the table will be throttled." That is framed around provisioned settings. We are on-demand, where the index scales with the table, so it is something to re-check if we switch modes, not a risk we carry today.
Figure 6 sketches the failure and the two documented ways out, none of which we have needed.
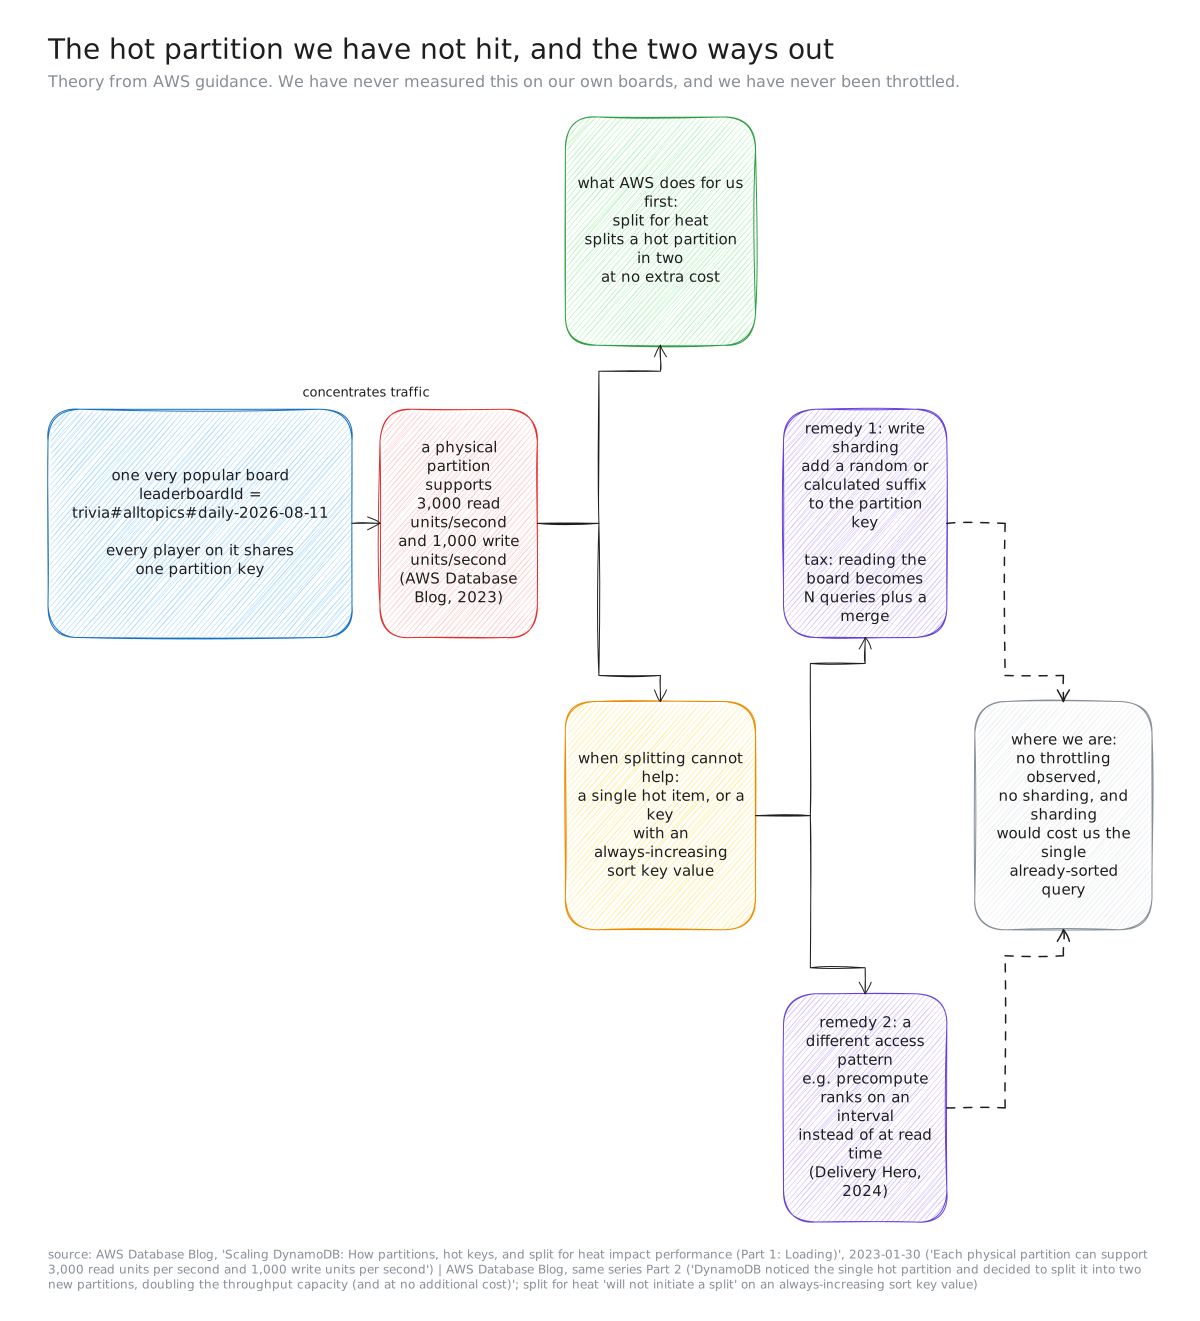
Figure 6. Theory from AWS guidance, not something we have needed or measured. We have never observed DynamoDB throttling on our tables.
If deep rank became the product, we'd add a sorted set, not replace DynamoDB
If live global rank for every player became the product, DynamoDB alone would be the wrong tool, and AWS says so. A sorted-set store answers it directly: "Rank computation is built into the data structure, not your application code", with "O(log N) rank lookups regardless of player count". The cost is a second service to run, and a sorted set is memory-bound.
The other direction is Delivery Hero's, published by AWS: a production leaderboard on DynamoDB alone, where "These leaderboards are computed and updated once at the end of the day". Precomputing rank on an interval makes everything cheap. It is the trade we did not want: a trivia round that ends should show its result now.
So we sit in between on purpose. If live deep rank becomes the feature, the sorted set goes next to DynamoDB, not instead of it.
Predictions vs outcome
| Prediction | What happened | Right? |
|---|---|---|
| One ascending read of inverted keys returns the board best-first, ties to the earliest | the four example keys sort exactly so (computed from the shipped builder) | Yes |
| A score is readable within 1 s at p95 | 210 ms run-wide on DEV; the worst size was 235 ms | Yes |
| Propagation slows as a board grows | flat: p50 158 to 160 ms from 100 to 10,000 players | No |
The INCLUDE projection saves write capacity (ADR-0010) | the docs say only above 1 KB; our entries are far under | Probably not |
| The histogram spreads writes (an earlier draft) | it bounds reads only; all 128 counters sit on one item | No |
| Partition capacity is the first limit a busy board hits | zero throttles recorded; failures began between 8 and 16 in flight | No |
| Those failures are transaction conflict on the counter row (the run's reading) | concurrency pinned at 10 while Lambda throttled 2,471 invocations; conflict caused at most 91 failures | No: Lambda throttles at a concurrency limit of 10 (re-checked 2026-09-28) |
Key takeaways
- Store items in the order you read them. If the sort key encodes rank, "the top N" is a read, not a computation.
- Invert only the component whose order you want reversed. Ours breaks ties by earliest achievement, which a plain descending read would get backwards.
- Keep bookkeeping rows out of an index by leaving out its key. An index entry exists only if the item carries the index's key attributes.
- Budget two index writes for every change to an indexed key. A delete of the old entry plus a put of the new one.
- Don't expect a hot item to split. DynamoDB can split a hot partition, never a hot item, and all our counters live on one.
- Return a range when you cannot afford an exact rank. DynamoDB has no order statistics; bound the cost and say it's an estimate.
What we still don't know
- What any of this costs in production. The production stack was created on 2026-09-26, and nothing here has been measured against it. Every measurement is DEV.
- Whether the 16-in-flight failures were throttles. Consistent with it, not provable: that level shares a five-minute metrics bucket with the 64 level, and the logs that would split them have expired.
- Whether a board's write capacity is ever the binding limit. We have zero throttles reported and nothing else.
- The metadata row's real consumed capacity. DynamoDB emits no per-item capacity metric; the 2,000 units and 29.1% share in our artifact are inferred from a table-level figure.
- How the rank-estimate interval behaves on a genuinely crowded board. We have a 2,501-row local run and nothing at scale.
- Whether our measurements survive a longer run. AWS's warning applies to us: "when benchmarking DynamoDB, don't assume that what you see in the first 5 minutes is what you'll see after an hour!"
What we would do next
- Repeat the sweep, which now records a reason per request, against the default three-board fan-out.
- Measure consumed write capacity on DEV against a populated board, and replace the arithmetic above with a real per-submission figure.
- Measure rank-estimate interval widths on a board of 100,000 or more, and set the display policy from the p99 width rather than intuition.
- Re-run the propagation harness with response caching on, and measure edge freshness separately rather than inferring it.
- Re-check the projection decision with real storage numbers, now that I know it probably saves nothing on write.
Further reading
Primary sources, all read in full on 2026-09-18 (UTC). Full notes, including quotes, section references and the pages that redirected or would not load, are in artifacts/blog/_research/dynamodb-foundations.md.
- DeCandia et al., "Dynamo: Amazon's Highly Available Key-value Store", SOSP 2007. https://www.allthingsdistributed.com/files/amazon-dynamo-sosp2007.pdf
- Elhemali et al., "Amazon DynamoDB: A Scalable, Predictably Performant, and Fully Managed NoSQL Database Service", USENIX ATC 2022. https://www.usenix.org/system/files/atc22-elhemali.pdf
- DynamoDB Developer Guide, "Core components": https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/HowItWorks.CoreComponents.html
- Developer Guide, "Improving data access with secondary indexes": https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/SecondaryIndexes.html
- Developer Guide, "Using Global Secondary Indexes": https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/GSI.html
- Developer Guide, "Take advantage of sparse indexes": https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/bp-indexes-general-sparse-indexes.html
- Developer Guide, "General guidelines for secondary indexes": https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/bp-indexes-general.html
- Developer Guide, "Best practices for using sort keys": https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/bp-sort-keys.html
- Developer Guide, "Using write sharding to distribute workloads evenly": https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/bp-partition-key-sharding.html
- Developer Guide, "Burst and adaptive capacity": https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/burst-adaptive-capacity.html
- Developer Guide, "DynamoDB Transactions: how it works". https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/transaction-apis.html
- Developer Guide, "DynamoDB throughput capacity": https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/capacity-mode.html
- Hunter and Natarajan, "Scaling DynamoDB: How partitions, hot keys, and split for heat impact performance", AWS Database Blog, 2023. https://aws.amazon.com/blogs/database/part-1-scaling-dynamodb-how-partitions-hot-keys-and-split-for-heat-impact-performance/
- Lopez Pazos, Carvalho Queiroz and Lee, "Player profiles to leaderboards: Choosing the right AWS database, Part 2", AWS for Games Blog, 2026. https://aws.amazon.com/blogs/gametech/player-profiles-to-leaderboards-choosing-the-right-aws-database-part-2/
- Zulich, "Amazon DynamoDB: Gaming use cases and design patterns", AWS Database Blog, 2019. https://aws.amazon.com/blogs/database/amazon-dynamodb-gaming-use-cases-and-design-patterns/
- Marinković, Paschoal, Idicula Watasseril and Schaaf, "How Delivery Hero perfects restaurant operations using gamification with Amazon DynamoDB", AWS Database Blog, 2024: https://aws.amazon.com/blogs/database/how-delivery-hero-perfects-restaurant-operations-using-gamification-with-amazon-dynamodb/
Evidence
Our configuration, read on 2026-09-18 from the online-leaderboard repository:
- Tables, index, billing mode, TTL, point-in-time recovery, deletion protection, and the absence of any
StreamSpecificationor event source mapping:template.yaml. - Sort-key format,
SCORE_CEILINGof 1,000,000,000,000, pad width 13:src/lib/score-key-builder.js,src/constants/score-limits.js. - The four
rankKeyvalues in Figure 2 and the bucket table: produced by calling the shippedbuildRankKeyandscoreToHistogramBucketon 2026-09-18. Player ids are invented. - Histogram, 128 buckets, 2,000-entry cap, range-not-point results:
src/lib/rank-percentile-calculator.js,docs/design/rank-percentile.md, ADR-0013. - Write path, conditions, idempotency records, three-item transaction:
src/handlers/submit-score-handler.js,src/lib/score-update-command-builder.js,src/lib/leaderboard-metadata-counter.js,src/lib/idempotency-record.js. - Read path,
ScanIndexForward,Limit, cursor:src/handlers/query-leaderboard-handler.js,src/lib/leaderboard-page-query-builder.js. - Default fan-out of three periods, one variant:
src/config/leaderboard-fanout-config.js. - Two COUNT queries per board and the
rankDelta: falseopt-out:contracts/README.md. - The reconciler is an offline two-pass recount:
src/lib/leaderboard-metadata-reconciler.js,tools/reconcile-leaderboard-metadata.mjs. - No production stack when this was written:
README.md, "Environments" ("The production deployment path exists, but the stack does not"). The stack went live on 2026-09-26: the overnight handoff for 2026-09-26, "Done before you slept" ("The leaderboard PROD stack is live", 57 resources). - Dates from
git logontemplate.yaml,docs/adrandsrc/lib/score-key-builder.js.
Measurements:
- Propagation percentiles, 300 samples, 0 errors, DEV
us-east-1, 2026-08-18T19:38:19.881Z, commit7e8a1cd:benchmarks/20260818T193819.881Z/report.mdandconfig.json. The earlier same-day run behind the target:benchmarks/20260818T094113.895Z/, cited in ADR-0012. - Concurrency outcomes, 6,868 peak-minute write units and zero throttles, DEV, 2026-08-19T01:35:30Z, commit
e3fb772:benchmarks/LFL26LEADBORD-035/metadata-counter-dev.json. - The 2,501-row rank run and its stated limits:
reports/LFL26LEADBORD-036/local-route-benchmark.json. - The Lambda concurrency limit of 10: the overnight handoff for 2026-09-26, entry 2026-09-27 ~10:55Z (
aws lambda get-account-settings:ConcurrentExecutions = 10); the increase to 1,000 was approved at 12:16Z the same day (entry ~14:20Z). The 2026-08-19 run's own metrics show concurrency pinned at 10 then too (next item). - Lambda throttles, not conflict, on 2026-08-19, and the re-run on 2026-09-28: leaderboard PR #102,
benchmarks/ice-breaker-147-submission-sweep/README.mdand itscloudwatch.json. The 2026-08-19 run's five-minute CloudWatch metrics: peakConcurrentExecutions10, 2,471 Lambda throttles, 2,562 API 5xx, 2,806 reservations against 2,715 committed transactions, 1,177TransactionConflict. The re-run repeats the ladder with a reason recorded per request.
Derived, not measured: every item-write count above and in Figure 4; the ~17 write request units and ~$0.32 a month; the histogram bucket boundaries; the 2,000 units and 29.1% share attributed to the metadata row, which the artifact itself labels inferred because DynamoDB emits table-level rather than item-level capacity metrics; the claim that most of the 159 ms is outside the index (the split was not measured).
Not measured at all: production anything; per-board write capacity; the reason any single submission failed on 2026-08-19 (the 2026-09-28 re-run records one); rank-estimate interval widths above 2,501 rows; edge freshness.
External sources: every quotation is linked inline and recorded with its access date, section reference and load result in artifacts/blog/_research/dynamodb-foundations.md. Sources that would not load (including four Developer Guide URLs that now redirect to the guide's front page) are listed there rather than cited.