
A test that passes the moment you write it is unproven. So on 2026-09-18 we spent a night breaking our own scripts one line at a time, to find out which tests could actually fail.
That night a web-side agent and a service-side agent moved Hearso's live trivia rooms onto a new Rust WebSocket service. A handful of small scripts decided whether that was going well: a health checker, a bot workload, a database invariants reader, and a runner judging a two-hour soak against seven numbered conditions.
Those scripts were the only thing between "the system is fine" and "nobody measured", and one had already fooled us. An Uptime Kuma checker wrote examined: 0 and exit 1 for three different causes: Kuma down, Kuma unreachable, or its credentials missing. Five coordinator runs went by before we could tell them apart.
So I wanted to know: were the rest of these scripts genuinely tested, or just accompanied by tests?
We hand-picked 51 mutants across three scripts, one deliberate change each, and ran the suite against every one.
Short answer: 47 died on the first pass, and the 4 that survived each named a test nobody had written. One more survivor, on another file earlier that day, named a line that shouldn't exist.
The catch is where it didn't help. Both real bugs of the night were in the thin wiring layer we had exempted as too simple to mutate.
A mutant is a smoke test for your tests
A smoke alarm that's never gone off isn't a working smoke alarm; it's an object on a ceiling. You hold something smoky under it and see what happens.
Precisely: a mutant is one deliberate change to the code under test: an operator flipped, a guard deleted, a constant moved by one. Run the suite. If a test goes red, the mutant is killed and that test is proven to hold that behaviour. If everything stays green, the mutant survived, and it has named a behaviour nothing checks.
Here's a real example. In our Kuma checker, up = values.count(1) became up = values.count(1) + values.count(2), so "pending" counted as up. One test went red, so that mutant died and the behaviour is pinned.
It mattered because these scripts decided whether a two-hour soak passed, and a green nobody can prove wrong isn't evidence.
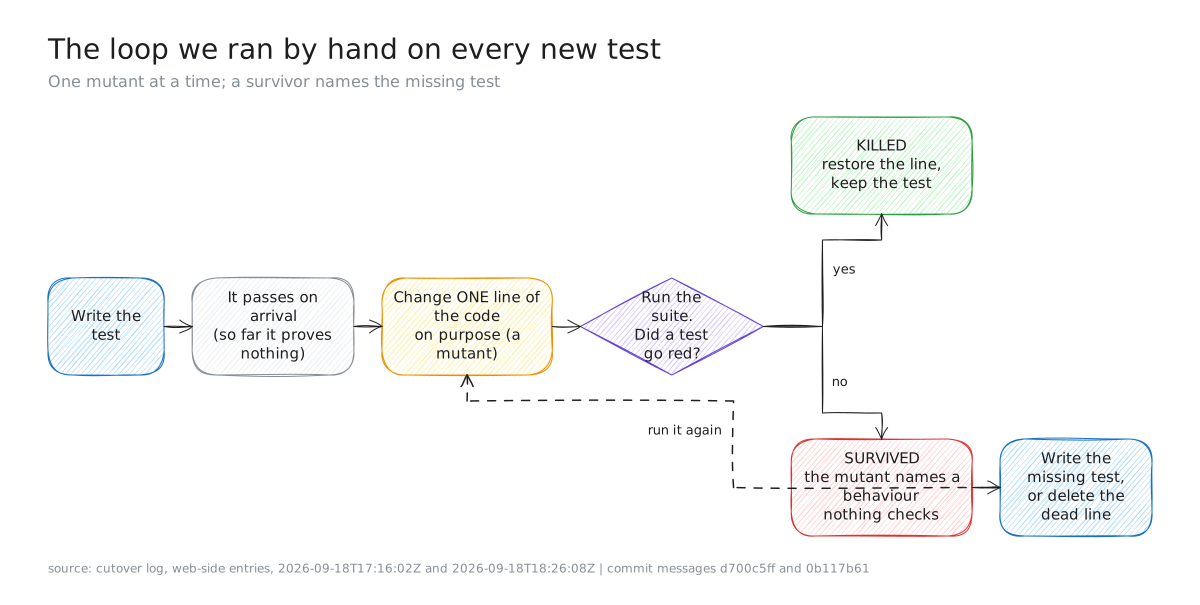
Figure 1. The loop we ran by hand on every new test. Of 51 mutants across three scripts on 2026-09-18 (UTC), 4 took the lower branch.
We picked every mutant by hand rather than generating them. These were files of a few hundred lines, and the mutants worth running were the ones you could name in a sentence.
One mutant, end to end
The replacement Kuma checker reads Kuma's Prometheus endpoint over plain HTTP and should be green only when every monitor is UP. Kuma encodes status as 1 UP, 0 DOWN, 2 PENDING, 3 MAINTENANCE.
# the code
up = values.count(1)
return (0 if values and up == len(values) else 1), {"examined": len(values), ...}

# the mutant: PENDING quietly counted as UP
up = values.count(1) + values.count(2)
# the test that kills it
def test_pending_is_not_up(self):
    code, ev = check.verdict(ENV, answers(200, row("a", 1) + row("b", 2)))
    self.assertEqual((code, ev["metrics"]["pending"]), (1, 1))
One line changed, one test red, mutant dead. The checker has 11 tests and took 8 mutants, and all 8 died:
- pending counted as up;
- an empty Kuma reported green;
- missing credentials reported red instead of "not configured";
- a 401 parsed as a 200;
- every metric row counted as a monitor;
examinedfloored at 1;- the configured Kuma address ignored;
http_statusdropped.
The count isn't the point. The point is that the checker now gives a different reading for each state it can meet, where the old one gave one reading for three causes:
| State | Exit code | Evidence |
|---|---|---|
| Real credentials, all monitors up | 0 | examined 7 |
| Wrong password | 1 | http_status 401 |
| No credentials | 125 | not configured |
| A URL nobody serves | 1 | http_status 0 |
What 51 mutants caught: four missing tests
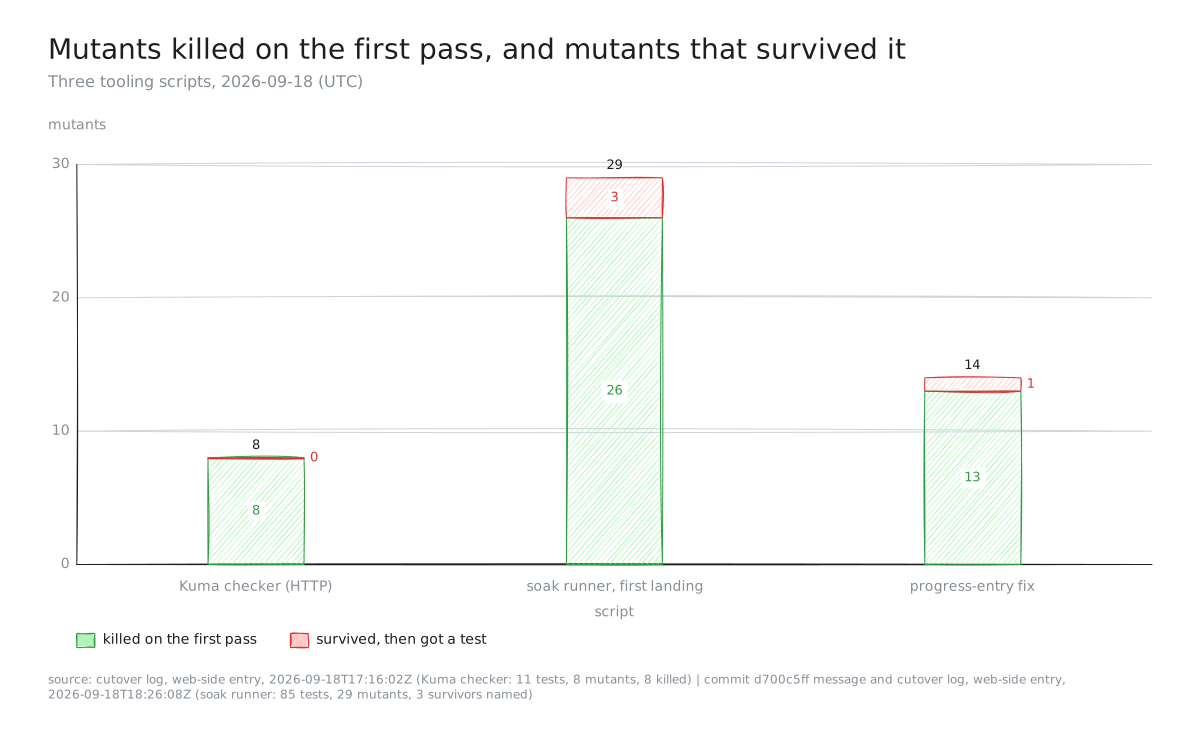
Figure 2. Every mutant run by hand against three tooling scripts on 2026-09-18 (UTC): 51 in total, 4 of which survived their first pass.
| Script | Tests | Mutants | Survived at first | Where |
|---|---|---|---|---|
| Kuma checker, plain HTTP | 11 | 8 | 0 | scratch, offered to the other side |
| Soak runner, first landing | 85 | 29 | 3 | commit d700c5ff |
| Lock adoption (a later change, outside the 51) | 94 | 1 named | 0 | commit 0b117b61 |
| Progress-entry fix | 153 | 14 | 1 | commit fe01e001 |
The soak runner's three survivors are the whole argument, because each named a test nobody had written:
-1passing a zero-condition. The runner marks an unmeasured number-1. Letting-1satisfy a "must be zero" condition broke no test, which is a soak passing by never measuring.- Memory from the first sample instead of minute 15. The rule is RSS growth under 10% from minute 15, to skip warm-up. Measuring from minute 0 still produced a number, and everything stayed green.
- No preflight. Removing the refusal to start (before the lock, before four GREEN runs exist, before the service answers) broke nothing.
Each got its test before the file landed. The lock-adoption change had one mutant worth naming, and it died: a birth time that's nearly right must not be accepted.
The progress-entry fix had one survivor, also given a test: a title that could say "healthy so far" above a list of named reasons it wasn't.
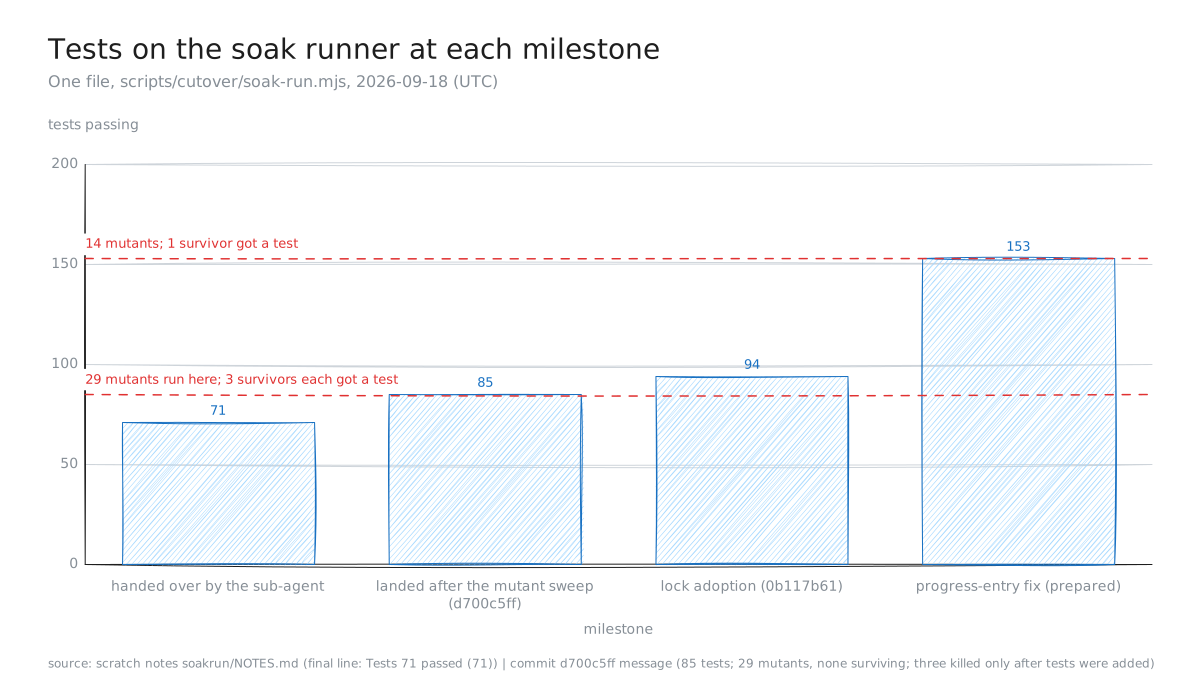
Figure 3. Tests passing on the soak runner at four points on 2026-09-18 (UTC): 71 as handed over, 85 landed, 94 after lock adoption, 153 in the progress-entry fix (commit fe01e001).
Figure 3 is one file growing: 71 tests as a delegated sub-agent handed it over, 85 when it landed after the mutant sweep, 94 with lock adoption, and 153 in the progress-entry fix. Not all 14 tests between 71 and 85 came from survivors: three did, by name, and the rest from the same review pass.
What it cost: about a minute of machine time
Less than it sounds, and I'm not going to invent a number for the part nobody timed.
The landing window stamped itself. It held the shared lock for seven seconds, from 18:25:16Z to 18:25:23Z. Inside it, the 85-test file ran in about 1 second (red at 18:25:17Z, green at 18:25:18Z), and the whole 770-test scripts suite in about 3 seconds (18:25:18Z to 18:25:21Z). At roughly a second a run, 29 mutants is under a minute of machine time.
The real cost is human: choosing a mutant worth running, and writing the test that kills it. That wasn't measured, so it isn't reported.
Where it didn't help
That is what a minute of machine time bought. This is what it did not buy, and it is the more useful half.
Hand-picked mutants aren't coverage
We chose mutants we could name, so we tested the properties we already had in mind. Eight mutants against a 40-line checker is a good afternoon, not a proof the checker is right.
Some mutants can't be killed, and that's a finding too
An equivalent mutant changes the code without changing its behaviour, so no test can catch it. Ours was on the browser's protocol codec: accepting a JSON list where a plain object is required broke nothing, because a list carries no v claim and is refused a step earlier anyway.
The guard was dead code, so we deleted it and retargeted the test at JSON null, which does throw without it. A survivor isn't always a missing test; sometimes it's a line that shouldn't exist.
The thin wiring stayed untested, and that's where the real bugs were
A test seam is the split between logic you can call with fake inputs and the wiring that touches the world. Here it was pure exported functions, plus a realDeps() object holding the process, network and filesystem calls.
The seam decided where a mutant could reach, so it also decided where a bug could sit unvisited. The runner's notes admitted it: "realDeps() was never executed. By me or by the tests." Both of the night's real bugs were in there:
greenRunAlive()usedpgrep -f <path>, which matches any process whose command line merely contains the path, our own monitoring shells included;- a missing signal handler let
SIGINTskip thefinallyand leave the lock directory on disk.
A fully tested function can still be wrong about its job
The runner built its half-hourly progress entry by running the end verdict over a run still in progress. That function had tests, and they passed.
Nobody had read a mid-run entry the way a stranger under time pressure would. The minute-30 entry of a healthy soak (106 games, 0 violations, memory 12% below baseline) listed nine failed conditions, and the other side stopped the run at minute 38. It was right to, given what the entry said.
No mutant could have found this, because no line was wrong. The function did what its tests said, on a run it was never meant to judge.
A green from a tool that didn't look is worse than a red
In that same seven-second window our scratch lint reported 0 errors on the two files: it had ignored both as outside its base path. We re-ran eslint inside the repository and didn't count the first result.
Our issue tracker had already named the shape. A coverage threshold is "a check whose null case reads as success. An excluded path reports as covered by being absent" (hearso-web issue #250).
Predictions vs outcome
| What we expected | What happened | Right? |
|---|---|---|
| The Kuma checker's tests pinned its behaviour | All 8 mutants died on the first pass | Yes |
| A mutant sweep would be cheap enough to run on every new test | About a second per run; 29 mutants in under a minute of machine time | Yes |
| The soak runner's zero-conditions were covered | Letting -1 pass a zero-condition broke no test | No |
| Every survivor would mean a missing test | One was an equivalent mutant: the fix was deleting a dead guard | No |
| The thin I/O layer was too simple to need mutants | Both real bugs of the night were in it | No |
| A tested verdict function would read correctly mid-run | Its minute-30 entry printed nine failures over a healthy soak | No |
Key takeaways
- If a test passed on arrival, it's unproven. Change one line and make sure something goes red.
- Treat a surviving mutant as the useful outcome. It names the test you didn't write, or the line you should delete.
- Give each real failure its own reading. Three causes collapsing into one
examined: 0cost five coordinator runs. - Mutate the wiring too. Ours was exempted as "thin", and both real bugs were in it.
- Remember what mutants can't tell you. They prove a test can fail, not that the pinned behaviour is the right one.
What I'd do next
Extract the wiring instead of exempting it. The progress-entry fix does that: coordinatorAlive(psText) and onStopSignal(emitter, cleanup, exit) are exported as pure functions so a mutant can reach them, leaving realDeps() as plumbing rather than a hiding place.
That fix waited for a while. It was prepared during the soak but held back, because the soak sampled the tree once a minute and any commit under a runtime path would have voided it.
Update, 2026-09-28: the fix landed later that night as commit fe01e001, after the final GREEN run; its message gives the same counts, 153 tests and 14 mutants.
I'd also keep the mutant list beside the file rather than in a scratch directory that dies with the session, and run the sweep as a command instead of a habit. It held for one night because two agents were checking each other, which is not a plan.
Our sibling repository already does this properly. online-leaderboard records a mutation score on every pull request: 91.05% (PR #46), 99.30% (PR #50), and 93.22% overall with the submit handler alone at 81.09% (PR #51). Each hearso-web pull request, meanwhile, states plainly "mutation: not measured in this repository" (PR #370).
That per-module split is our own lesson in someone else's numbers: one blanket score hides the module nobody attacked.
How we measured
The harness was twenty lines of Python: back up the file, apply one anchored replacement, run vitest (or the Python tests), restore, and diff to prove the restore. Every mutant was chosen by hand and run one at a time.
Timings come from the landing window's own stamps, not a benchmark. We didn't time the human part, and we didn't run a mutation tool, so there is no mutation score here to compare with anyone else's.
Evidence
All times UTC, all 2026-09-18.
| Claim | Source |
|---|---|
| Kuma checker: 11 tests, 8 mutants, 8 killed; the eight named; five runs lost | cutover log, web-side entry 17:16:02Z |
Four states, four readings (exit 0/1/125; http_status 200/401/0) | same entry; kuma/check-kuma-http.py, kuma/test_check_kuma_http.py |
test_pending_is_not_up and the up = values.count(1) line | kuma/test_check_kuma_http.py; kuma/check-kuma-http.py |
| Soak runner: 85 tests, 29 mutants, none surviving at landing; the three first-pass survivors named | commit d700c5ff; cutover log, web-side entry 18:26:08Z |
| Lock adoption: 94 tests; the near-match mutant killed | commit 0b117b61 |
| Progress-entry fix: 153 tests (94 before), 14 mutants, one survivor named | soakrun2/commit3.txt; landed as commit fe01e001 (cutover log, web-side entry 22:15:20Z) |
| 71 tests as handed over by the sub-agent | soakrun/NOTES.md, final line |
1 second for 85 tests; 3 seconds for the 770-test scripts suite | soakrun/window.status, 18:25:17Z–18:25:21Z |
| The landing window: lock held 18:25:16Z to 18:25:23Z, 7 seconds; the scratch lint ignored both files and was not counted, eslint 0 inside the repository | cutover log, web-side entry 18:26:08Z |
The harness: back up, one anchored replacement, run, restore, diff | scratch files mutate.py, mutate2.py |
| Equivalent mutant: a JSON list accepted where an object is required | cutover log, web-side entry 08:38:11Z |
"realDeps() was never executed: by me or by the tests" | soakrun/NOTES.md, "Unsure / not verified" |
pgrep -f self-match, found by the other side at 19:14Z | cutover log, web-side entry 19:31:35Z |
No signal handler; SIGINT skipped finally | cutover log, web-side entry 19:54:35Z; service-side entry 19:53:32Z |
| Minute-30 entry: nine failed conditions on 106 games, 0 violations, RSS 12% below baseline | cutover log, web-side entries 19:44:43Z and 19:54:35Z |
| Scratch lint reported 0 errors on two files it had ignored | cutover log, web-side entry 18:26:08Z |
coordinatorAlive and onStopSignal exported so they can be tested | soakrun2/NOTES.md; commit fe01e001 |
| "A check whose null case reads as success" (coverage denominator) | hearso-web issue #250, closed 2026-09-06 |
| Sibling mutation scores 91.05%, 99.30%, 93.22% (submit handler 81.09%) | online-leaderboard PRs #46, #50, #51 |
| "mutation: not measured in this repository" on hearso-web PRs | hearso-web PR #370, merged 2026-09-09 |